Implementation Details of Cartoon-VAE-DDPM
Published:
Variational Autoencoder (VAE) learns to compress data into a latent Gaussian space and reconstruct it in a single shot. Denoising Diffusion Probabilistic Model (DDPM) tackles the same evidence-lower-bound objective from another direction: it begins with pure noise and iteratively denoise through hundreds of steps, exchanging speed for high-fidelity, stable synthesis. Both frameworks connect random noise to data, yet VAE rely on an explicit encoder–decoder pair, whereas DDPM use a learned Markov chain that inverts a forward noising process. This blog traces the progression from VAE to DDPM, clarifying their shared principles, with code examples available at this repository.
Part I: Variational Autoencoders (VAE)
We begin with the VAE’s latent-variable model, derive its variational training objective, and connect the reconstruction and KL terms to the implementation.
1. Image Generation as a Maximum-Likelihood Problem
Given a dataset \(\mathcal{D}=\{x^{(i)}\}_{i=1}^{N}\), we want to learn a distribution over images from which new images can be generated. A variational autoencoder (VAE) approaches this through a latent-variable generative model.
1.1 Notation
Variables and network parameters
Symbol Meaning \(x\in\mathbb{R}^{D}\) An image represented by its pixel values. During a single-example loss calculation, \(x\) is fixed. \(z\in\mathbb{R}^{d}\) An unobserved latent vector; the dataset provides no corresponding latent labels. \(\theta\) Decoder network’s trainable parameters. \(\phi\) Encoder network’s trainable parameters. \(N\) Number of training images. \(D,d\) Image dimension and latent dimension, respectively. Distributions
Distribution Statistical meaning Role \(p(z)\) Prior over latent variables Usually fixed as \(\mathcal{N}(0,I)\). \(p_\theta(x\mid z)\) Conditional image (observation) likelihood Probabilistic (Gaussian) decoder. \(p_\theta(x,z)\) Joint distribution Complete generative model. \(p_\theta(x)\) Marginal likelihood, or evidence Quantity targeted by maximum likelihood. \(p_\theta(z\mid x)\) Exact posterior under the current model Implied by the prior and decoder. \(q_\phi(z\mid x)\) Approximate posterior Probabilistic encoder. For continuous variables, these functions represent probability densities, not probabilities of individual exact vectors.
1.2 Generative model and marginalization
The model generates an image in two stages:
\[z\sim p(z)=\mathcal{N}(0,I), \qquad x\sim p_\theta(x\mid z).\]The decoder takes a latent vector and predicts distribution parameters in pixel space. For example, a Gaussian decoder predicts an image-shaped mean. We can sample pixels from its distribution or display the mean directly. The decoder distribution need not be Gaussian. (Doersch, 2016)
The probability chain rule gives
\[\boxed{ p_\theta(x,z)=p(z)p_\theta(x\mid z). }\]Because the dataset contains images but not their latent variables, the image likelihood includes all possible latent explanations:
\[\boxed{ p_\theta(x) = \int p_\theta(x,z)\,dz = \int p(z)p_\theta(x\mid z)\,dz. }\]The joint distribution is not a replacement objective. It connects the image to its hidden explanation; marginalizing it gives the image likelihood.
1.3 Maximum likelihood estimation
For independent training images, maximum likelihood estimation (MLE) seeks
\[\begin{aligned} &\max_\theta \sum_{i=1}^{N}\log p_\theta(x^{(i)}) \\ &\qquad= \max_\theta \sum_{i=1}^{N} \log\int p(z)p_\theta(x^{(i)}\mid z)\,dz. \end{aligned}\]Evaluating the decoder likelihood at a specified latent code is generally straightforward. The difficulty is integrating over all codes: nonlinear neural decoders generally lack an analytical marginal likelihood, while accurate numerical integration can be expensive. (Kingma and Welling, 2013)
2. Variational Inference: Approximating the Latent Posterior
2.1 Bayesian inference
Fix the current decoder parameters \(\theta\) and observe an image \(x\). Bayes’ rule defines the distribution of latent codes that could explain it:
\[\boxed{ p_\theta(z\mid x) = \frac{p(z)p_\theta(x\mid z)} {\int p(z')p_\theta(x\mid z')\,dz'}. }\]Conceptually, each candidate latent code goes forward through the decoder. We evaluate how well its predicted distribution explains the observed image, weight this by the code’s prior density, and normalize across all candidates.
This does not mean feeding the image into the decoder or reversing the network. The posterior depends on the same \(\theta\) because Bayes’ rule uses the decoder likelihood. “Exact” means exact under the current model, even if that model poorly represents real images.
The normalization requires the same difficult marginal likelihood, so ordinary VAE training does not explicitly calculate this posterior. (Kingma and Welling, 2019)
2.2 From inference to optimization
Variational inference replaces difficult posterior computation with optimization over a tractable family of distributions. For a fixed image and decoder, the approximation target is
\[\boxed{ \min_\phi D_{\mathrm{KL}}\!\left( q_\phi(z\mid x)\,\Vert\,p_\theta(z\mid x) \right), \qquad x,\theta\text{ fixed}. }\]Both distributions concern the same latent variable conditioned on the same image. We approximate a distribution of explanations, rather than select one latent vector. (Blei et al., 2017)
A common encoder parameterization is
\[\boxed{ q_\phi(z\mid x) = \mathcal{N}\!\left( z; \mu_\phi(x), \operatorname{diag}\!\left(\sigma_\phi^2(x)\right) \right). }\]Unlike the decoder, the encoder takes the image as input and predicts latent means and standard deviations. Sharing this network across images is amortized variational inference. Choosing a Gaussian approximation does not imply that the exact posterior is Gaussian. (Kingma and Welling, 2019)
The target KL still involves the intractable posterior. We therefore need an equivalent encoder-training objective that avoids evaluating its normalization.
3. The Evidence Lower Bound and VAE Loss
3.1 Deriving the ELBO
For a fixed image \(x\), expectations are taken over latent codes sampled from the encoder distribution:
\[\mathbb{E}_{q_\phi(z\mid x)}[f(z)] = \int q_\phi(z\mid x)f(z)\,dz.\]By definition, the KL divergence between the approximate and exact posteriors is
\[\begin{aligned} &D_{\mathrm{KL}}\!\left( q_\phi(z\mid x)\,\Vert\,p_\theta(z\mid x) \right) \\[4pt] &= \int q_\phi(z\mid x) \log\frac{q_\phi(z\mid x)}{p_\theta(z\mid x)} \,dz \\[4pt] &= \int q_\phi(z\mid x) \left[ \log q_\phi(z\mid x) - \log p_\theta(z\mid x) \right]dz \\[4pt] &= \mathbb{E}_{q_\phi(z\mid x)}\!\left[ \log q_\phi(z\mid x) - \log p_\theta(z\mid x) \right]. \end{aligned}\]The second equality uses the logarithm-of-a-ratio identity. The last equality uses the expectation–integral identity with
\[f(z) = \log q_\phi(z\mid x) - \log p_\theta(z\mid x).\]Next, Bayes’ rule gives
\[p_\theta(z\mid x) = \frac{p_\theta(x,z)}{p_\theta(x)},\]so
\[\log p_\theta(z\mid x) = \log p_\theta(x,z) - \log p_\theta(x).\]Substituting this into the KL expression and using linearity of expectation,
\[\begin{aligned} &D_{\mathrm{KL}}\!\left( q_\phi(z\mid x)\,\Vert\,p_\theta(z\mid x) \right) \\[4pt] &= \mathbb{E}_{q_\phi(z\mid x)}\!\left[ \log q_\phi(z\mid x) - \log p_\theta(x,z) + \log p_\theta(x) \right] \\[4pt] &= \mathbb{E}_{q_\phi(z\mid x)}\!\left[ \log q_\phi(z\mid x) - \log p_\theta(x,z) \right] + \mathbb{E}_{q_\phi(z\mid x)}[\log p_\theta(x)]. \end{aligned}\]The evidence term leaves the expectation because it does not depend on the integration variable \(z\). With \(x\) and \(\theta\) fixed, the expectation–integral identity gives
\[\begin{aligned} \mathbb{E}_{q_\phi(z\mid x)}[\log p_\theta(x)] &= \int q_\phi(z\mid x)\log p_\theta(x)\,dz \\[4pt] &= \log p_\theta(x) \underbrace{ \int q_\phi(z\mid x)\,dz }_{1} \\[4pt] &= \log p_\theta(x). \end{aligned}\]The integral equals one because the encoder distribution is normalized. Therefore,
\[\begin{aligned} &D_{\mathrm{KL}}\!\left( q_\phi(z\mid x)\,\Vert\,p_\theta(z\mid x) \right) \\[4pt] &= \log p_\theta(x) - \mathbb{E}_{q_\phi(z\mid x)}\!\left[ \log p_\theta(x,z) - \log q_\phi(z\mid x) \right]. \end{aligned}\]Define the evidence lower bound (ELBO):
\[\boxed{ \mathcal{E}(\theta,\phi;x) = \mathbb{E}_{q_\phi(z\mid x)}\!\left[ \log p_\theta(x,z) - \log q_\phi(z\mid x) \right]. }\]Consequently,
\[\begin{aligned} \log p_\theta(x) &= \mathcal{E}(\theta,\phi;x) + D_{\mathrm{KL}}\!\left( q_\phi(z\mid x)\,\Vert\,p_\theta(z\mid x) \right) \\[4pt] &\geq \mathcal{E}(\theta,\phi;x). \end{aligned}\]The inequality follows from nonnegative KL divergence. For fixed \(\theta\), maximizing the ELBO over \(\phi\) minimizes posterior-approximation error. Equality holds when the approximate and exact posteriors coincide; otherwise, the ELBO is a surrogate for the MLE objective. (Blei et al., 2017)
3.2 Recovering the two loss terms
Substitute the generative factorization of the joint:
\[\begin{aligned} \mathcal{E}(\theta,\phi;x) &= \mathbb{E}_{q_\phi(z\mid x)}\!\left[ \log p_\theta(x\mid z) + \log p(z) - \log q_\phi(z\mid x) \right] \\[4pt] &= \mathbb{E}_{q_\phi(z\mid x)}[\log p_\theta(x\mid z)] - D_{\mathrm{KL}}\!\left( q_\phi(z\mid x)\,\Vert\,p(z) \right). \end{aligned}\]Negating the ELBO gives the minimized loss:
\[\boxed{ \begin{aligned} \mathcal{J}(\theta,\phi;x) ={}& \underbrace{ -\mathbb{E}_{q_\phi(z\mid x)}[\log p_\theta(x\mid z)] }_{\text{reconstruction loss}} \\[4pt] &+ \underbrace{ D_{\mathrm{KL}}\!\left( q_\phi(z\mid x)\,\Vert\,p(z) \right) }_{\text{prior-matching KL}}. \end{aligned} }\]The original image is the \(x\) inside the reconstruction term. Whereas \(p_\theta(\,\cdot\mid z)\) denotes the predicted distribution, \(p_\theta(x\mid z)\) is its scalar density evaluated at the observed image. Its negative logarithm penalizes predictions that explain that image poorly. (Kingma and Welling, 2013)
The explicit KL penalizes departure from the prior. It differs from the posterior KL measuring the ELBO’s gap. Together, reconstruction and prior matching implement the variational objective.
Across the dataset, training solves
\[\min_{\theta,\phi} \frac{1}{N} \sum_{i=1}^{N} \mathcal{J}(\theta,\phi;x^{(i)}).\]3.3 Concrete Gaussian terms
Choose a fixed-variance Gaussian decoder:
\[p_\theta(x\mid z) = \mathcal{N}\!\left(x;m_\theta(z),\tau^2I\right).\]Its negative log-likelihood is
\[-\log p_\theta(x\mid z) = \frac{1}{2\tau^2} \sum_{j=1}^{D} \left(x_j-m_{\theta,j}(z)\right)^2 + C,\]where
\[C=\frac{D}{2}\log(2\pi\tau^2).\]This explicitly compares original pixel values with predicted pixel means. The reconstruction term averages that comparison over encoder samples:
\[-\mathbb{E}_{q_\phi(z\mid x)}[\log p_\theta(x\mid z)] = \frac{ \mathbb{E}_{q_\phi(z\mid x)} [\lVert x-m_\theta(z)\rVert^2] }{2\tau^2} + C.\]Squared error therefore follows from a fixed-variance Gaussian likelihood. A Bernoulli likelihood for binary pixels instead produces binary cross-entropy. (Doersch, 2016)
For the diagonal-Gaussian encoder, abbreviate its outputs as \(\mu_j=\mu_{\phi,j}(x)\) and \(\sigma_j=\sigma_{\phi,j}(x)\). Using
\[\begin{aligned} \mathbb{E}_{q_\phi(z\mid x)}[(z_j-\mu_j)^2]&=\sigma_j^2,\\ \mathbb{E}_{q_\phi(z\mid x)}[z_j^2]&=\mu_j^2+\sigma_j^2, \end{aligned}\]the KL to the standard-normal prior becomes
\[\boxed{ D_{\mathrm{KL}}\!\left( q_\phi(z\mid x)\,\Vert\,p(z) \right) = \frac12\sum_{j=1}^{d} \left( \mu_j^2+\sigma_j^2-1-\log\sigma_j^2 \right). }\]3.4 Sampling and joint training
Estimate the reconstruction expectation using the reparameterization trick:
\[\epsilon\sim\mathcal{N}(0,I), \qquad z=\mu_\phi(x)+\sigma_\phi(x)\odot\epsilon.\]Here \(\odot\) denotes elementwise multiplication. This produces image-dependent encoder samples while preserving a differentiable path through their parameters. A one-sample loss estimate is
\[\widehat{\mathcal{J}} = -\log p_\theta(x\mid z) + D_{\mathrm{KL}}\!\left( q_\phi(z\mid x)\,\Vert\,p(z) \right).\]The same image is both the encoder input and reconstruction target. We evaluate its likelihood without needing to sample another noisy image. With a fixed prior and separate weights, the decoder receives reconstruction gradients; the encoder receives both reconstruction and KL gradients. (Kingma and Welling, 2013; Rezende et al., 2014)
After training, unconditional generation samples \(z\sim p(z)\) and uses the decoder, without the encoder.
The prior is chosen, the exact posterior is implied, and the encoder learns an approximation. The VAE loss connects them through a lower bound on image likelihood.
3.5 VAE Implementation
To connect the Gaussian loss to the implementation, let
x_recondenote the decoder mean \(m_\theta(z)\). Each \(x_j\) is an observed pixel-channel value normalized to \([-1,1]\); an RGB \(64\times64\) image has \(D=3\times64\times64=12{,}288\) such values. Vector notation is only shorthand: the code keeps image-shaped tensors.With observation variance \(\tau^2\) (
\[p_\theta(x_j\mid z) = \frac{1}{\sqrt{2\pi\tau^2}} \exp\!\left[-\frac{(x_j-m_{\theta,j}(z))^2}{2\tau^2}\right].\]sigma_x^2below), each value has densityThe covariance \(\tau^2I\) makes these values independent conditional on \(z\), so the image density is
\[p_\theta(x\mid z)=\prod_{j=1}^{D}p_\theta(x_j\mid z).\]Taking the negative logarithm turns the product into a sum, recovering Section 3.3’s reconstruction loss:
\[-\log p_\theta(x\mid z) = \frac{D}{2}\log(2\pi\tau^2) + \frac{1}{2\tau^2}\sum_{j=1}^{D}(x_j-m_{\theta,j}(z))^2.\]For fixed \(\tau^2\), the first term is constant and can be omitted during training. The code uses summed squared error with coefficient one; with
\[\frac{1}{2\tau^2}=1 \quad\Longrightarrow\quad \tau^2=\frac12.\]KL_WEIGHT = 1, its Gaussian interpretation isThus, the fixed observation variance is implicit in the loss coefficient, in normalized pixel units; no decoder standard-deviation tensor is needed. It is separate from the encoder’s learned latent variance, which enters the analytic KL term. Using one sampled \(z\) per image gives the following minibatch loss, up to the omitted constant:
# --- 4) Loss function ---
# Interpret p(x | z) as Normal(x_recon, sigma_x^2 * I) with fixed pixel variance.
# Gaussian negative log likelihood = sum((x-x_recon)^2)/(2*sigma_x^2) + constant.
# This unit-weight summed MSE, with KL_WEIGHT=1, corresponds to sigma_x^2=0.5
# (std=1/sqrt(2)) in normalized pixel units. No decoder std tensor is needed.
mse = nn.MSELoss(reduction='sum')
def loss_fn(x_recon, x, mu, logvar):
    # x_recon uses one sampled z, giving a Monte Carlo estimate of expected NLL.
    recon_loss = mse(x_recon, x)
    # mu and logvar describe latent q(z | x), separate from the pixel variance.
    kl_loss = -0.5 * torch.sum(1 + logvar - mu.pow(2) - logvar.exp())
    total_loss = recon_loss + KL_WEIGHT * kl_loss
    return total_loss, recon_loss, kl_loss
VAE training result is illustrated below, full implementation can be found at this repository.
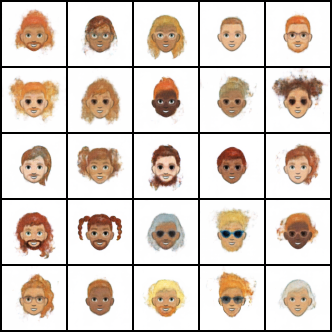
VAE sampling result. Trained with z_dim = 512, epochs = 100.
Part II: Denoising Diffusion Probabilistic Models (DDPM)
A variational autoencoder connects a latent variable to an observed image through a decoder. DDPM instead introduces a sequence of latent states and generates an image through repeated denoising.
4. DDPM as a Hierarchical Latent-Variable Model
DDPM construction involves two probability models: a prescribed forward-noising process \(q\), and a learned reverse-generation process \(p_\theta\).
The distinction between modeling choices and derived distributions is important. We choose Gaussian transition families for the forward and learned reverse processes. Other Gaussian distributions, including the clean-conditioned reverse posterior, follow mathematically from these choices. (Ho et al., 2020)
4.1 Variables, distributions, and the connection to VAE
Following the notation in Part I, let an image have \(D\) scalar coordinates. DDPM introduces states
\[x_0,x_1,\ldots,x_T,\]where \(x_0\) is a clean image and the remaining states represent progressively corrupted versions of it under the forward process.
Symbol Meaning \(x_0\) The observed clean image during training, or the final output during generation. \(x_t\in\mathbb{R}^D\) An intermediate noisy image at timestep \(t\), generally containing both signal and noise. \(z=x_{1:T}\) The complete latent variable: the collection \((x_1,\ldots,x_T)\). \(q\) The probability model defined by the forward-noising process. \(p_\theta\) The learned generative probability model. \(\theta\) Trainable parameters of the denoising network. \(\epsilon_\theta(x_t,t)\) The network’s prediction of noise from a noisy image and its timestep. All intermediate states have the same dimensionality as the observed image. Calling them latent variables does not mean that they must be low-dimensional or pure noise; it means that the dataset does not provide them as observations.
The correspondence to VAE is:
Role VAE DDPM Observed variable \(x\) \(x_0\) Complete latent variable \(z\) \(z=x_{1:T}\) Variational distribution Learned encoder \(q_\phi(z\mid x)\) Fixed noising process \(q(x_{1:T}\mid x_0)\) Prior over all latents \(p(z)\) \(p_\theta(x_{1:T})\) Observation likelihood \(p_\theta(x\mid z)\) \(p_\theta(x_0\mid x_1)\) Exact model posterior \(p_\theta(z\mid x)\) \(p_\theta(x_{1:T}\mid x_0)\) The prior over the complete latent trajectory
Since \(z=x_{1:T}\), the notation \(p_\theta(z)\) refers to the joint distribution of all latent states before conditioning on an observed image. To identify this distribution, separate the final observation-generating step from the reverse-process factorization:
\[\begin{aligned} p_\theta(x_0,z) &= p(x_T) \left[ \prod_{t=2}^{T}p_\theta(x_{t-1}\mid x_t) \right] p_\theta(x_0\mid x_1). \end{aligned}\]The factors inside the first part generate only the latent states: first \(x_T\), then \(x_{T-1}\), and eventually \(x_1\). The final factor generates the observed image \(x_0\). This gives the grouping
\[\boxed{ p_\theta(x_0,z) = \underbrace{ p(x_T)\prod_{t=2}^{T}p_\theta(x_{t-1}\mid x_t) }_{p_\theta(z)} p_\theta(x_0\mid x_1). }\]This factorization is the DDPM counterpart of the VAE factorization \(p_\theta(x,z)=p(z)p_\theta(x\mid z)\). (Ho et al., 2020)
More formally, the latent-path prior is obtained by marginalizing out the observation. For discrete images, sum over all possible image values \(u\):
\[\begin{aligned} p_\theta(z) &= \sum_u p_\theta(u,z)\\[4pt] &= p(x_T) \left[ \prod_{t=2}^{T}p_\theta(x_{t-1}\mid x_t) \right] \underbrace{ \sum_u p_\theta(u\mid x_1) }_{1}\\[4pt] &= p(x_T)\prod_{t=2}^{T}p_\theta(x_{t-1}\mid x_t). \end{aligned}\]For a continuous observation likelihood, the sum over \(u\) is replaced by an integral, which also equals one. Thus, marginalizing the observation removes the normalized final decoder factor and leaves the joint distribution of the latent trajectory.
The word prior means that this distribution is not conditioned on the observed image. It does not require the distribution to be fixed, independent of \(\theta\), or standard Gaussian. In DDPM, only the starting prior \(p(x_T)=\mathcal{N}(0,I)\) is prescribed to be standard Gaussian. The complete latent-path prior \(p_\theta(z)\) also contains the learned transitions and therefore depends on \(\theta\).
Observation likelihood conditions only on the last latent state
The complete observation likelihood is \(p_\theta(x_0\mid z)\). Using the factorization above,
\[\begin{aligned} p_\theta(x_0\mid z) &= \frac{p_\theta(x_0,z)}{p_\theta(z)}\\[4pt] &= \frac{ p_\theta(z)p_\theta(x_0\mid x_1) }{ p_\theta(z) }\\[4pt] &= p_\theta(x_0\mid x_1). \end{aligned}\]Therefore,
\[\boxed{ p_\theta(x_0\mid x_1,\ldots,x_T) = p_\theta(x_0\mid x_1). }\]This simplification follows from the reverse model’s Markov structure, not from the Gaussian assumption. Once \(x_1\) is known, the earlier generative states provide no additional information for the final transition. Those states have not disappeared from the model: they still determine the distribution of \(x_1\).
The marginal likelihood and maximum likelihood estimation:
Like a VAE, DDPM defines the probability of an observed image by integrating out its latent variables:
\[\boxed{ \begin{aligned} p_\theta(x_0) &= \int p_\theta(x_0,z)\,dz\\[4pt] &= \int p_\theta(x_0\mid z)p_\theta(z)\,dz\\[4pt] &= \int p_\theta(x_0\mid x_1) p(x_T) \left[ \prod_{t=2}^{T}p_\theta(x_{t-1}\mid x_t) \right] \,dx_{1:T}, \end{aligned} }\]where \(dx_{1:T}=dx_1\cdots dx_T\).
Although the final conditional likelihood depends only on \(x_1\), the marginal likelihood averages over the entire latent trajectory that can lead to it. Accordingly, \(p_\theta(x_0\mid x_1)\) and \(p_\theta(x_0)\) are different quantities: the former is the observation likelihood given a latent state, while the latter is the model’s likelihood of the observed image alone.
For a dataset of \(N\) independent clean images, the maximum likelihood estimation problem is
\[\boxed{ \hat\theta_{\mathrm{MLE}} \in \operatorname*{arg\,max}_{\theta} \frac1N\sum_{n=1}^{N} \log p_\theta\!\left(x_0^{(n)}\right). }\]This is the same marginal-likelihood principle used for VAE models, with a hierarchical latent trajectory replacing the single latent layer. The expression above states the exact likelihood-based objective; the practical DDPM training loss will be derived separately. (Kingma and Welling, 2013)
Finally, the exact model posterior is
\[\boxed{ p_\theta(z\mid x_0) = \frac{p_\theta(x_0,z)}{p_\theta(x_0)} = \frac{ p_\theta(x_0\mid x_1)p_\theta(z) }{ p_\theta(x_0) }. }\]This posterior is implied by the learned generator. It is distinct from the prescribed forward-noising distribution \(q(z\mid x_0)\). The latter is exactly specified as a corruption process, but serves as an approximate inference distribution for the former.
4.2 The forward model and the original DDPM noise schedule
Choose a sequence of forward variances \(\beta_1,\ldots,\beta_T\), and define
\[\alpha_t=1-\beta_t, \qquad \bar\alpha_t=\prod_{s=1}^{t}\alpha_s, \qquad \bar\alpha_0=1.\]The original DDPM experiments use \(T=1000\), with variances increasing linearly from \(10^{-4}\) to \(0.02\). Images are scaled to \([-1,1]\). (Ho et al., 2020, Section 4)
Explicitly, the schedule is
\[\boxed{ \begin{aligned} \beta_t &= \beta_1+\frac{t-1}{T-1}(\beta_T-\beta_1)\\[4pt] &= 10^{-4}+\frac{t-1}{999}(0.02-10^{-4}), \qquad t=1,\ldots,1000. \end{aligned} }\]The linear progression is across diffusion timesteps, not training iterations. These values remain fixed throughout training.
The forward process is chosen to be a Markov chain:
\[\boxed{ q(x_{1:T}\mid x_0) = \prod_{t=1}^{T}q(x_t\mid x_{t-1}), }\]with Gaussian transitions
\[\boxed{ q(x_t\mid x_{t-1}) = \mathcal{N}\!\left( x_t;\sqrt{\alpha_t}x_{t-1},\beta_t I \right). }\]Equivalently, one step is sampled as
\[x_t = \sqrt{\alpha_t}x_{t-1} + \sqrt{\beta_t}\eta_t, \qquad \eta_t\sim\mathcal{N}(0,I),\]where the forward noises are independent across steps and independent of the clean image.
Thus, \(\beta_t\) is the variance of the newly added noise, while \(\sqrt{\beta_t}\) is its standard deviation. Each step attenuates the previous state and adds Gaussian noise.
4.3 The reverse model and its variance convention
Generation starts from the prescribed top-level prior
\[\boxed{ p(x_T)=\mathcal{N}(x_T;0,I) }\]and proceeds through the reverse chain
\[x_T\rightarrow x_{T-1}\rightarrow\cdots\rightarrow x_0.\]The joint model is
\[\boxed{ p_\theta(x_{0:T}) = p(x_T)\prod_{t=1}^{T}p_\theta(x_{t-1}\mid x_t). }\]For intermediate steps, we choose
\[\boxed{ p_\theta(x_{t-1}\mid x_t) = \mathcal{N}\!\left( x_{t-1};\mu_\theta(x_t,t),\sigma_t^2 I \right), \qquad t\geq2. }\]The Gaussian form of this learned reverse conditional is a modeling choice. It does not assert that the true reverse conditional \(q(x_{t-1}\mid x_t)\) is exactly Gaussian. The model is a Markov chain with Gaussian conditional distributions; its full joint distribution need not be Gaussian.
The original DDPM considers two prescribed reverse-variance schedules:
\[\sigma_t^2=\beta_t \qquad\text{or}\qquad \sigma_t^2=\tilde\beta_t.\]The derivation in this post adopts
\[\boxed{ \sigma_t^2=\tilde\beta_t, \qquad t\geq2, }\]where \(\tilde\beta_t\) is derived in Section 5.3. This is one of the fixed-variance choices investigated in the paper, rather than a unique mandatory DDPM setting. (Ho et al., 2020, Section 3.2)
“Fixed variance” means that the variance is prescribed rather than learned. It may differ between timesteps, but for a given timestep it does not depend on the image or the network parameters. Unlike the forward \(\beta_t\) schedule, the resulting \(\tilde\beta_t\) schedule is not generally linear.
The final observation likelihood \(p_\theta(x_0\mid x_1)\) is handled separately. For discrete image pixels, the original DDPM uses a discretized Gaussian decoder. Its positive underlying variance must be specified separately rather than set equal to \(\tilde\beta_1=0\). The reconstruction-loss section will explain this distinction. (Ho et al., 2020, Section 3.3)
Finally, distinguish the top-level prior from the prior over the complete latent path:
\[\boxed{ p_\theta(z) = p_\theta(x_{1:T}) = p(x_T)\prod_{t=2}^{T}p_\theta(x_{t-1}\mid x_t). }\]Only \(p(x_T)\) is prescribed to be standard Gaussian. The other latent distributions are determined by the learned reverse transitions.
5. Forward Diffusion and the Analytic Denoising Target
The forward process serves two purposes. It constructs noisy training inputs, and it provides an analytically computable distribution that can supervise each learned reverse transition.
The first requires \(q(x_t\mid x_0)\). The second requires \(q(x_{t-1}\mid x_t,x_0)\). These distributions answer different questions.
5.1 Construct a noisy image at an arbitrary timestep
Fix the clean image \(x_0\). Let \(m_t\) be the conditional mean, and let \(v_t\) denote the scalar coefficient of the conditional covariance:
\[m_t:=\mathbb{E}_q[x_t\mid x_0], \qquad \operatorname{Cov}_q(x_t\mid x_0)=v_t I.\]Thus, \(v_t\) describes the accumulated conditional variance at timestep \(t\), not just the variance of the noise introduced in that one step. The latter is \(\beta_t\).
Starting from
\[x_t=\sqrt{\alpha_t}x_{t-1}+\sqrt{\beta_t}\eta_t,\]the zero mean of \(\eta_t\) gives
\[m_t=\sqrt{\alpha_t}m_{t-1}, \qquad m_0=x_0.\]Repeated substitution therefore yields
\[m_t=\sqrt{\bar\alpha_t}x_0.\]For the covariance, scaling a random vector by a scalar multiplies its covariance by the square of that scalar. Also, the fresh noise \(\eta_t\) is independent of \(x_{t-1}\) conditional on the fixed \(x_0\), so the cross-covariance terms vanish. (can be added together for total variance) Therefore,
\[\begin{aligned} \operatorname{Cov}_q(x_t\mid x_0) &= \alpha_t\operatorname{Cov}_q(x_{t-1}\mid x_0) + \beta_t\operatorname{Cov}(\eta_t)\\[4pt] &= \alpha_t v_{t-1}I+\beta_t I. \end{aligned}\]Matching the scalar coefficients of \(I\) gives the recursion
\[\boxed{ v_t=\alpha_t v_{t-1}+\beta_t, \qquad v_0=0. }\]The initial variance is zero because \(x_0\) is held fixed in this conditional calculation. The term \(\alpha_t v_{t-1}\) is the retained variance from earlier steps; \(\beta_t\) is the newly added variance.
The solution is
\[\boxed{v_t=1-\bar\alpha_t.}\]To verify it, the initial condition satisfies \(v_0=0=1-\bar\alpha_0\). If \(v_{t-1}=1-\bar\alpha_{t-1}\), then
\[\begin{aligned} v_t &=\alpha_t(1-\bar\alpha_{t-1})+\beta_t\\[4pt] &=(\alpha_t+\beta_t)-\alpha_t\bar\alpha_{t-1}\\[4pt] &=1-\bar\alpha_t. \end{aligned}\]The bar is essential: \(v_{t-1}=1-\bar\alpha_{t-1}\), whereas \(1-\alpha_{t-1}=\beta_{t-1}\) describes only one step’s added variance. For example,
\[v_1=\beta_1, \qquad v_2=\alpha_2\beta_1+\beta_2 =1-\alpha_1\alpha_2.\]Conditioned on \(x_0\), the state is an affine combination of independent Gaussian noises, so it is Gaussian. Its mean and covariance above therefore give
\[\boxed{ q(x_t\mid x_0) = \mathcal{N}\!\left( x_t;\sqrt{\bar\alpha_t}x_0, (1-\bar\alpha_t)I \right). }\]Consequently, a sample at timestep \(t\) can be generated directly:
\[\boxed{ x_t = \sqrt{\bar\alpha_t}x_0 + \sqrt{1-\bar\alpha_t}\epsilon, \qquad \epsilon\sim\mathcal{N}(0,I). } \tag{1}\]This direct noising formula is part of the standard DDPM construction. (Ho et al., 2020, Equation (4))
The first term is the retained clean signal; the second is the accumulated noise. Here, \(\epsilon\) denotes the normalized aggregate noise in this direct formula, not necessarily the noise from the last individual forward step.
Equation (1) allows training to select any timestep without simulating all earlier states. It samples the required marginal distribution; independently using the formula at several timesteps is not the same as sampling an entire Markov trajectory.
5.2 Why the terminal state approaches standard Gaussian noise
At the final timestep,
\[x_T = \sqrt{\bar\alpha_T}x_0 + \sqrt{1-\bar\alpha_T}\epsilon.\]When \(\bar\alpha_T\) is small, the clean-signal contribution becomes small and the noise coefficient approaches one.
For the original 1000-step linear schedule, evaluating the product gives
\[\bar\alpha_{1000} = \prod_{t=1}^{1000}(1-\beta_t) \approx4.0358\times10^{-5}.\]Therefore,
\[x_{1000} \approx 0.006353\,x_0+0.999980\,\epsilon.\]This explains why the endpoint is close to standard Gaussian noise, while also showing that the clean contribution has not vanished exactly.
For every fixed \(x_0\), the conditional distribution \(q(x_t\mid x_0)\) is already Gaussian. The terminal approximation is more specific:
\[q(x_T\mid x_0)\approx\mathcal{N}(0,I),\]with a mean close to zero and covariance close to \(I\), nearly independent of the original image.
This does not imply that the marginal \(q(x_t)\), obtained by averaging over different clean images, is Gaussian at every timestep. Such an average generally combines Gaussians with different means.
5.3 Derive a tractable reverse target by conditioning on the clean image
During training, \(x_0\) is known. We can therefore ask:
Given this clean image and its noisy version at timestep \(t\), what previous noisy states are plausible?
The answer is the local posterior
\[q(x_{t-1}\mid x_t,x_0).\]Conditional Bayes’ rule and Gaussian square completion give
\[\boxed{ q(x_{t-1}\mid x_t,x_0) = \mathcal{N}\!\left( x_{t-1};\tilde\mu_t(x_t,x_0),\tilde\beta_t I \right), \qquad t\geq2, } \tag{2}\]where
\[\boxed{ \tilde\mu_t(x_t,x_0) = \frac{\sqrt{\alpha_t}(1-\bar\alpha_{t-1})} {1-\bar\alpha_t}x_t + \frac{\sqrt{\bar\alpha_{t-1}}\beta_t} {1-\bar\alpha_t}x_0 } \tag{3}\]and
\[\boxed{ \tilde\beta_t = \frac{1-\bar\alpha_{t-1}}{1-\bar\alpha_t}\beta_t. } \tag{4}\]These are the analytic posterior parameters from DDPM. The full derivation of Equations (2)-(4) is given in Appendix A. (Ho et al., 2020, Equations (6)-(7))
The Gaussian form here is a derived consequence of the linear-Gaussian forward process. This is different from choosing a Gaussian family for the learned reverse model.
The parameters have a direct statistical meaning:
\[\tilde\mu_t(x_t,x_0) = \mathbb{E}_q[x_{t-1}\mid x_t,x_0],\] \[\tilde\beta_t I = \operatorname{Cov}_q(x_{t-1}\mid x_t,x_0).\]Thus, Equation (3) describes the mean of possible previous states, not a deterministic identity for \(x_{t-1}\). It combines information about the current noisy state with information about its clean origin.
The variance in Equation (4) depends only on the forward schedule, not on \(x_t\) or \(x_0\). This is why it can also be used as a fixed reverse-model variance during generation, when the clean image is unavailable.
Under the convention adopted in Section 4.3,
\[\boxed{ \sigma_t^2=\tilde\beta_t, \qquad \sigma_t = \sqrt{ \frac{1-\bar\alpha_{t-1}}{1-\bar\alpha_t}\beta_t }, \quad t\geq2. }\]The square root is the standard deviation multiplying fresh noise in reverse sampling. The authors’ implementation precomputes such variance schedules and retrieves their values using the timestep. (DDPM implementation)
5.4 Why this posterior is useful for training
The target distribution and learned distribution play different roles:
Analytic target Learned reverse model Distribution \(q(x_{t-1}\mid x_t,x_0)\) \(p_\theta(x_{t-1}\mid x_t)\) Mean \(\tilde\mu_t(x_t,x_0)\) \(\mu_\theta(x_t,t)\) Variance Derived \(\tilde\beta_t I\) Prescribed \(\sigma_t^2 I\) Uses the true clean image? Yes, to construct the training target. No. The likelihood-bound derivation will produce local comparisons of the form
\[D_{\mathrm{KL}}\!\left( q(x_{t-1}\mid x_t,x_0) \,\Vert\, p_\theta(x_{t-1}\mid x_t) \right).\]Equations (3) and (4) make the first distribution explicitly available. Because both distributions are Gaussian, this comparison can be evaluated analytically and converted into a prediction loss.
Conditioning the target on \(x_0\) does not add \(x_0\) to the network input. The clean image provides supervision during training; the learned reverse transition must operate using only the current noisy image and timestep.
6. From Maximum Likelihood to the DDPM Objective
Section 4 defined DDPM as a latent-variable generative model, while Section 5 derived the tractable posterior \(q(x_{t-1}\mid x_t,x_0)\). We now connect these two results: why should matching this local posterior help train a model that generates complete images? The connection comes from a variational lower bound on the image likelihood.
The derivation has two stages. First, we replace the difficult marginal-likelihood objective with a variational bound, following the same principle as VAE. Second, we rewrite that bound into terms associated with individual reverse transitions. The algebraic details of the second stage are provided in Appendix B.
6.1 Deriving the evidence lower bound
Recall the maximum likelihood problem introduced in Section 4.1:
\[\max_\theta \frac1N\sum_{n=1}^{N} \log p_\theta\!\left(x_0^{(n)}\right).\]For one fixed clean image \(x_0\), its marginal likelihood is
\[p_\theta(x_0) = \int p_\theta(x_0,z)\,dz, \qquad z=x_{1:T}.\]The integral averages over the complete latent trajectory. Although the joint density can be evaluated for a specified trajectory, directly evaluating this marginal is generally difficult. As in VAE, we introduce a tractable variational distribution: in this case, the fixed forward process \(q(z\mid x_0)\). (Kingma and Welling, 2013)
Multiplying and dividing the integrand by this density gives
\[\begin{aligned} \log p_\theta(x_0) &= \log\int q(z\mid x_0) \frac{p_\theta(x_0,z)}{q(z\mid x_0)} \,dz\\[4pt] &= \log \mathbb{E}_{q(z\mid x_0)} \left[ \frac{p_\theta(x_0,z)}{q(z\mid x_0)} \right]\\[4pt] &\geq \mathbb{E}_{q(z\mid x_0)} \left[ \log\frac{p_\theta(x_0,z)}{q(z\mid x_0)} \right]. \end{aligned}\]The second equality uses the definition of expectation. The inequality uses Jensen’s inequality: because \(\log\) is concave,
\[\log\mathbb{E}[U]\geq\mathbb{E}[\log U]\]for a positive random variable \(U\) with the required expectations defined.
Define the right-hand side as the evidence lower bound:
\[\boxed{ \mathrm{ELBO}_\theta(x_0) = \mathbb{E}_{q(z\mid x_0)} \left[ \log p_\theta(x_0,z)-\log q(z\mid x_0) \right]. }\]The posterior-KL identity derived for VAE in Section 3.1 applies here as well:
\[\boxed{ \begin{aligned} \log p_\theta(x_0) ={}& \mathrm{ELBO}_\theta(x_0)\\[4pt] &+ D_{\mathrm{KL}}\!\left( q(z\mid x_0)\,\Vert\,p_\theta(z\mid x_0) \right). \end{aligned} }\]The nonnegative KL measures the gap between the bound and the exact log-likelihood. Consequently, maximizing the ELBO is a variational surrogate for maximum likelihood, not generally the same optimization problem. Equality holds when the variational distribution equals the exact model posterior. (Kingma and Welling, 2013)
For minimization, define the negative ELBO:
\[\boxed{ \begin{aligned} \mathcal{L}_{\mathrm{bound}}(x_0) &:=-\mathrm{ELBO}_\theta(x_0)\\[4pt] &= \mathbb{E}_{q(z\mid x_0)} \left[ \log\frac{q(z\mid x_0)}{p_\theta(x_0,z)} \right]\\[4pt] &= \mathbb{E}_{q(x_{1:T}\mid x_0)} \left[ \log \frac{q(x_{1:T}\mid x_0)} {p_\theta(x_{0:T})} \right]. \end{aligned} } \tag{5}\]The ratio reverses because
\[-\log\frac{p}{q} = \log\frac{q}{p}.\]The expectation remains under the same forward distribution. The final line of Equation (5) also expands the latent-variable notation:
\[\begin{aligned} z=x_{1:T}&=(x_1,\ldots,x_T),\\[4pt] x_{0:T}&=(x_0,x_1,\ldots,x_T)=(x_0,z). \end{aligned}\]Therefore,
\[\boxed{p_\theta(x_{0:T})=p_\theta(x_0,z).}\]The denominator has not been replaced by the latent-path prior \(p_\theta(z)=p_\theta(x_{1:T})\). The notation \(x_{0:T}\) includes the observed image as well as the latent states. No variable has been removed or integrated out in this change of notation.
Negating the bound also reverses the inequality:
\[\boxed{ -\log p_\theta(x_0) \leq \mathcal{L}_{\mathrm{bound}}(x_0). }\]Thus, we maximize a lower bound on log-likelihood, or equivalently minimize an upper bound on negative log-likelihood.
6.2 Rewriting the bound using reverse-oriented conditionals
Equation (5) involves the whole latent trajectory. To expose local training terms, we rewrite the forward-path density in reverse order:
\[\boxed{ q(x_{1:T}\mid x_0) = q(x_T\mid x_0) \prod_{t=2}^{T}q(x_{t-1}\mid x_t,x_0). } \tag{6}\]This identity follows from conditional Bayes’ rule and cancellation of intermediate density factors, as shown in Appendix B.1.
Equation (6) is the same forward-path distribution written differently. It is not the learned reverse model. In particular, the factors on the right remain conditioned on the known clean image.
The generative model has the corresponding factorization
\[p_\theta(x_{0:T}) = p(x_T) \left[ \prod_{t=2}^{T}p_\theta(x_{t-1}\mid x_t) \right] p_\theta(x_0\mid x_1).\]Substituting both factorizations into the log ratio in Equation (5),
\[\boxed{ \begin{aligned} \log \frac{q(x_{1:T}\mid x_0)} {p_\theta(x_{0:T})} ={}& \log\frac{q(x_T\mid x_0)}{p(x_T)} \\[4pt] &+ \sum_{t=2}^{T} \log \frac{q(x_{t-1}\mid x_t,x_0)} {p_\theta(x_{t-1}\mid x_t)} \\[4pt] &- \log p_\theta(x_0\mid x_1). \end{aligned} } \tag{7}\]The intermediate ratios now compare two distributions over the same previous-state variable \(x_{t-1}\). That alignment is what allows their expectations to become local KL divergences.
For one fixed timestep, write \(y=x_{t-1}\). The corresponding log ratio depends only on \(y,x_t\), and the fixed \(x_0\). Integrating out the other latent states leaves the two-state marginal, which factors as
\[q(y,x_t\mid x_0) = q(x_t\mid x_0)q(y\mid x_t,x_0).\]Therefore,
\[\begin{aligned} &\mathbb{E}_{q(x_{1:T}\mid x_0)} \left[ \log\frac{q(y\mid x_t,x_0)}{p_\theta(y\mid x_t)} \right]\\[4pt] &= \int q(x_t\mid x_0) \left[ \int q(y\mid x_t,x_0) \log\frac{q(y\mid x_t,x_0)}{p_\theta(y\mid x_t)} \,dy \right]dx_t\\[4pt] &= \mathbb{E}_{q(x_t\mid x_0)} \left[ D_{\mathrm{KL}}\!\left( q(x_{t-1}\mid x_t,x_0) \,\Vert\, p_\theta(x_{t-1}\mid x_t) \right) \right]. \end{aligned}\]The inner integral evaluates a KL over the possible previous states, holding \(x_t,x_0\) fixed. Its value still depends on \(x_t\), so the outer integral averages it over different noisy images produced from the same clean image.
These are different averages, not two ways of integrating over the same variable. The timestep itself is fixed during this calculation; the sum over timesteps comes afterward.
6.3 The complete objective and the role of each term
Applying the same marginalization to the terminal and reconstruction terms gives
\[\boxed{ \begin{aligned} \mathcal{L}_{\mathrm{bound}}(x_0) ={}& D_{\mathrm{KL}}\!\left( q(x_T\mid x_0)\,\Vert\,p(x_T) \right) \\[4pt] &+ \sum_{t=2}^{T} \mathbb{E}_{q(x_t\mid x_0)} \left[ D_{\mathrm{KL}}\!\left( q(x_{t-1}\mid x_t,x_0) \,\Vert\, p_\theta(x_{t-1}\mid x_t) \right) \right] \\[4pt] &- \mathbb{E}_{q(x_1\mid x_0)} \left[ \log p_\theta(x_0\mid x_1) \right]. \end{aligned} } \tag{8}\]This is the DDPM variational-loss decomposition. It expresses one global likelihood bound as a terminal-prior term, intermediate denoising terms, and a final reconstruction term. (Ho et al., 2020, Equation (5))
Terminal-prior matching. Define
\[C_{\mathrm{prior}}(x_0) = D_{\mathrm{KL}}\!\left( q(x_T\mid x_0)\,\Vert\,p(x_T) \right).\]This measures the mismatch between the endpoint of forward noising and the Gaussian prior used to start generation. With the fixed schedule and prior adopted in Section 4, it contains no trainable parameters:
\[\nabla_\theta C_{\mathrm{prior}}(x_0)=0.\]It can therefore be omitted when computing training gradients, although it remains part of the numerical value of the bound. Being independent of \(\theta\) does not mean that it is exactly zero. (Ho et al., 2020)
Intermediate denoising. For \(t\geq2\), define
\[J_t(x_0) = \mathbb{E}_{q(x_t\mid x_0)} \left[ D_{\mathrm{KL}}\!\left( q(x_{t-1}\mid x_t,x_0) \,\Vert\, p_\theta(x_{t-1}\mid x_t) \right) \right].\]The analytic posterior is the training target; the learned reverse transition is the prediction.
Both distributions describe possible values of \(x_{t-1}\). The KL does not compare the marginal distribution of an image at timestep \(t-1\) with the marginal distribution at timestep \(t\).
The target uses the clean training image to determine what previous states are plausible. The learned transition must approximate the target using only \(x_t\) and \(t\). Conditioning the target on \(x_0\) does not add \(x_0\) to the network input.
Final reconstruction. Define
\[J_1(x_0) = -\mathbb{E}_{q(x_1\mid x_0)} \left[ \log p_\theta(x_0\mid x_1) \right].\]This term evaluates how much likelihood the final decoder assigns to the known clean image after observing its slightly corrupted version \(x_1\).
The original path expectation reduces to
\[\begin{aligned} &-\mathbb{E}_{q(x_{1:T}\mid x_0)} [\log p_\theta(x_0\mid x_1)]\\[4pt] &= -\int q(x_1\mid x_0) \log p_\theta(x_0\mid x_1)\,dx_1, \end{aligned}\]because the other latent variables do not appear in the log-likelihood.
There is no integration over \(x_0\): it is the fixed observation being evaluated. The intermediate KL sum starts at \(t=2\), because \(q(x_0\mid x_1,x_0)\) is a point mass rather than another nondegenerate Gaussian posterior. The final step is kept as an observation negative log-likelihood.
For the discrete-pixel model specified in Section 4.3, this uses the discretized Gaussian decoder. No approximation of that likelihood has been made in Equation (8). (Ho et al., 2020, Section 3.3)
Using these labels,
\[\boxed{ \mathcal{L}_{\mathrm{bound}}(x_0) = C_{\mathrm{prior}}(x_0) + \sum_{t=2}^{T}J_t(x_0) + J_1(x_0). }\]The dataset-level variational objective is
\[\boxed{ \min_\theta \frac1N\sum_{n=1}^{N} \mathcal{L}_{\mathrm{bound}}\!\left(x_0^{(n)}\right). }\]The factorization, marginalization, and identification of KL terms have only rewritten the bound. They have not introduced a new approximation or changed its value.
6.4 The VAE correspondence and the next step
The connection to the VAE loss becomes explicit by grouping all latent transitions into the prior \(p_\theta(z)\):
\[p_\theta(x_0,z) = p_\theta(z)p_\theta(x_0\mid x_1).\]Substituting this factorization into Equation (5),
\[\boxed{ \begin{aligned} \mathcal{L}_{\mathrm{bound}}(x_0) ={}& D_{\mathrm{KL}}\!\left( q(z\mid x_0)\,\Vert\,p_\theta(z) \right) \\[4pt] &- \mathbb{E}_{q(z\mid x_0)} [\log p_\theta(x_0\mid x_1)]. \end{aligned} }\]This has the same prior-matching plus reconstruction structure as the VAE loss in Section 3.2. In DDPM, the structured latent-prior KL decomposes into several terms:
\[\boxed{ D_{\mathrm{KL}}\!\left( q(z\mid x_0)\,\Vert\,p_\theta(z) \right) = C_{\mathrm{prior}}(x_0) + \sum_{t=2}^{T}J_t(x_0). }\]Do not confuse this prior-matching KL with the posterior KL in the ELBO-gap identity:
\[\begin{aligned} D_{\mathrm{KL}}\!\left( q(z\mid x_0)\,\Vert\,p_\theta(z) \right) &:\ \text{a component of the loss},\\[6pt] D_{\mathrm{KL}}\!\left( q(z\mid x_0)\,\Vert\,p_\theta(z\mid x_0) \right) &:\ \text{the gap from the exact log-likelihood}. \end{aligned}\]The same distinction appears in the VAE derivation. (Kingma and Welling, 2013)
We can now see the purpose of the calculations in Section 5 and Appendix A. The objective contains
\[D_{\mathrm{KL}}\!\left( \underbrace{q(x_{t-1}\mid x_t,x_0)}_{\text{known target}} \,\Vert\, \underbrace{p_\theta(x_{t-1}\mid x_t)}_{\text{learned model}} \right).\]Appendix A supplies the target’s mean \(\tilde\mu_t(x_t,x_0)\) and covariance \(\tilde\beta_t I\). Section 4 supplies the learned Gaussian family and its prescribed covariance. The abstract distribution-matching objective is therefore computable. Gaussian KL evaluation is the next step toward the practical prediction loss. (Ho et al., 2020)
Section 7 will carry out that evaluation, convert mean matching into noise prediction, and distinguish the exact variational objective from DDPM’s simplified training loss.
7. From Gaussian KL to Noise-Prediction Training
Section 6 expressed the negative ELBO as
\[\mathcal{L}_{\mathrm{bound}}(x_0) = C_{\mathrm{prior}}(x_0) + \sum_{t=2}^{T}J_t(x_0) + J_1(x_0).\]The intermediate terms compare the analytic posterior from Section 5 with the learned reverse transition. We now evaluate those comparisons and convert them into a loss that can train the noise-prediction network.
Throughout this section, we retain the fixed reverse-variance convention introduced in Section 4.3:
\[\sigma_t^2=\tilde\beta_t, \qquad t\geq2.\]We first keep the formulas general enough to show where the variance enters. The detailed Gaussian calculations and the final decoder treatment are provided in Appendix C.
7.1 Evaluating the local Gaussian KL
For one fixed timestep \(t\geq2\), the target distribution is
\[q(x_{t-1}\mid x_t,x_0) = \mathcal{N}\!\left( x_{t-1}; \tilde\mu_t(x_t,x_0), \tilde\beta_t I \right),\]while the learned reverse transition is
\[p_\theta(x_{t-1}\mid x_t) = \mathcal{N}\!\left( x_{t-1}; \mu_\theta(x_t,t), \sigma_t^2 I \right).\]When evaluating their KL, \(x_t\) and \(x_0\) are fixed. Both distributions describe possible values of the same previous state \(x_{t-1}\).
Substituting the Gaussian density formulas into the KL definition gives
\[\boxed{ \begin{aligned} &D_{\mathrm{KL}}\!\left( q(x_{t-1}\mid x_t,x_0) \,\Vert\, p_\theta(x_{t-1}\mid x_t) \right)\\[4pt] &= \frac{ \lVert\tilde\mu_t(x_t,x_0)-\mu_\theta(x_t,t)\rVert^2 }{ 2\sigma_t^2 } +C_t, \end{aligned} } \tag{9}\]where
\[C_t = \frac D2 \left[ \frac{\tilde\beta_t}{\sigma_t^2} -1+ \log\frac{\sigma_t^2}{\tilde\beta_t} \right].\]Here, \(D\) is the number of scalar image coordinates. Appendix C.1 derives this expression by taking the expectation of the Gaussian log-density ratio.
With prescribed variances, \(C_t\) does not depend on \(\theta\). Under our particular choice \(\sigma_t^2=\tilde\beta_t\),
\[C_t=0.\]Consequently, the intermediate loss becomes
\[J_t(x_0) = \mathbb{E}_{q(x_t\mid x_0)} \left[ \frac{ \lVert\tilde\mu_t(x_t,x_0)-\mu_\theta(x_t,t)\rVert^2 }{ 2\sigma_t^2 } \right] +C_t.\]Distribution matching has reduced to weighted mean prediction. The analytic posterior mean \(\tilde\mu_t(x_t,x_0)\) is the target, and \(\mu_\theta(x_t,t)\) is the prediction.
The expectation over \(x_{t-1}\) has already been evaluated analytically inside the KL. Only the average over noisy inputs \(x_t\) remains. This is the fixed-variance Gaussian reduction used in the original DDPM derivation. (Ho et al., 2020)
7.2 Parameterizing the reverse mean through predicted noise
The model could predict the reverse mean directly. DDPM instead uses a network that predicts the noise in a corrupted image, then converts that prediction into the reverse mean. These are different parameterizations of the same Gaussian transition family. (Nichol and Dhariwal, 2021)
Recall the direct noising formula from Equation (1):
\[x_t = \sqrt{\bar\alpha_t}x_0 + \sqrt{1-\bar\alpha_t}\epsilon, \qquad \epsilon\sim\mathcal{N}(0,I).\]Rearranging,
\[x_0 = \frac{ x_t-\sqrt{1-\bar\alpha_t}\epsilon }{ \sqrt{\bar\alpha_t} }.\]Substituting this expression into the analytic posterior mean in Equation (3) gives
\[\boxed{ \tilde\mu_t(x_t,x_0) = \frac1{\sqrt{\alpha_t}} \left( x_t- \frac{\beta_t}{\sqrt{1-\bar\alpha_t}}\epsilon \right). } \tag{10}\]Appendix C.2 shows the substitution explicitly.
Equation (10) has not removed the clean image from the training construction: \(x_t\) was created using \(x_0\) and \(\epsilon\). It has rewritten the target mean in terms of quantities already available when constructing that training example.
Now define the learned mean by replacing the injected noise with a prediction:
\[\boxed{ \mu_\theta(x_t,t) := \frac1{\sqrt{\alpha_t}} \left( x_t- \frac{\beta_t}{\sqrt{1-\bar\alpha_t}} \epsilon_\theta(x_t,t) \right). } \tag{11}\]The network receives only \(x_t\) and \(t\). It does not receive the true noise or the clean image.
Subtracting Equations (10) and (11),
\[\tilde\mu_t-\mu_\theta = \frac{\beta_t} {\sqrt{\alpha_t}\sqrt{1-\bar\alpha_t}} \left( \epsilon_\theta(x_t,t)-\epsilon \right).\]Therefore,
\[\lVert\tilde\mu_t-\mu_\theta\rVert^2 = \frac{\beta_t^2} {\alpha_t(1-\bar\alpha_t)} \lVert\epsilon-\epsilon_\theta(x_t,t)\rVert^2.\]Substituting into Equation (9),
\[\boxed{ \begin{aligned} &D_{\mathrm{KL}}\!\left( q(x_{t-1}\mid x_t,x_0) \,\Vert\, p_\theta(x_{t-1}\mid x_t) \right)\\[4pt] &= w_t \lVert\epsilon-\epsilon_\theta(x_t,t)\rVert^2 +C_t, \\[6pt] &w_t := \frac{\beta_t^2} {2\sigma_t^2\alpha_t(1-\bar\alpha_t)}. \end{aligned} } \tag{12}\]The weighting coefficient has two sources:
\[\boxed{ w_t = \underbrace{\frac1{2\sigma_t^2}}_{\text{Gaussian KL}} \underbrace{ \left( \frac{\beta_t} {\sqrt{\alpha_t}\sqrt{1-\bar\alpha_t}} \right)^2 }_{\text{noise error to mean error}}. }\]It is not an arbitrary hyperparameter introduced after the derivation.
For the reverse variance used in this post,
\[\sigma_t^2 = \frac{1-\bar\alpha_{t-1}}{1-\bar\alpha_t}\beta_t,\]the coefficient simplifies to
\[\boxed{ w_t = \frac{\beta_t} {2\alpha_t(1-\bar\alpha_{t-1})}, \qquad t\geq2. }\]The intermediate training term can now be written as
\[\boxed{ J_t(x_0) = \mathbb{E}_{\epsilon\sim\mathcal{N}(0,I)} \left[ w_t \lVert\epsilon-\epsilon_\theta(x_t,t)\rVert^2 \right] +C_t, }\]where \(x_t\) is constructed from \(x_0\) and the sampled \(\epsilon\).
This expression is equal to the original local KL expectation. We have changed how it is calculated, not changed the objective.
7.3 What does the network’s output represent?
The supervised-learning interpretation is now explicit:
\[\boxed{ \text{input}=(x_t,t), \qquad \text{target}=\epsilon. }\]The target is the normalized aggregate noise used in the direct noising formula. It is not the simple difference \(x_t-x_0\), because the forward process also scales the clean signal.
The noise prediction determines a corresponding clean-image estimate:
\[\boxed{ \hat x_{0,\theta}(x_t,t) = \frac{ x_t-\sqrt{1-\bar\alpha_t}\epsilon_\theta(x_t,t) }{ \sqrt{\bar\alpha_t} }. }\]This follows by replacing the true noise with its prediction in the rearranged forward equation.
The learned reverse mean can equivalently be calculated by inserting this clean-image estimate into the analytic posterior-mean formula:
\[\boxed{ \mu_\theta(x_t,t) = \tilde\mu_t\!\left( x_t,\hat x_{0,\theta}(x_t,t) \right). }\]Thus, the two means use different sources of clean-image information:
\[\begin{aligned} \text{Training target:}\quad &\tilde\mu_t(x_t,x_0),\\[4pt] \text{Learned prediction:}\quad &\tilde\mu_t\!\left(x_t,\hat x_{0,\theta}(x_t,t)\right). \end{aligned}\]The authors’ implementation includes this conversion from predicted noise to a clean estimate and then to the reverse mean. (DDPM implementation)
The network is not expected to identify the exact injected noise perfectly for every input. Different clean-image/noise pairs can produce compatible noisy observations. Under squared-error regression, the unrestricted population-optimal predictor is
\[\epsilon^*(x_t,t) = \mathbb{E}[\epsilon\mid x_t,t],\]where the expectation includes the data distribution and forward corruption. This is a conditional estimate, not access to the hidden clean origin.
7.4 Treating the final reconstruction term
The intermediate derivation applies to \(t\geq2\). The final contribution remains
\[J_1(x_0) = -\mathbb{E}_{q(x_1\mid x_0)} [\log p_\theta(x_0\mid x_1)].\]Section 4 specified a discretized Gaussian observation model. For 8-bit images scaled to \([-1,1]\), the observed pixels lie on a discrete grid, even though the intermediate noisy states are continuous. The original DDPM assigns probability to a pixel by integrating a Gaussian density over its quantization bin. (Ho et al., 2020, Section 3.3)
Let \(b_i^-,b_i^+\) be the bin boundaries associated with the observed pixel \(x_0^i\). Then
\[\boxed{ p_\theta(x_0\mid x_1) = \prod_{i=1}^{D} \int_{b_i^-}^{b_i^+} \mathcal{N}\!\left( r;\mu_\theta^i(x_1,1),\sigma_1^2 \right)\,dr. }\]The positive decoder variance is specified separately from the intermediate rule. For concreteness, take
\[\sigma_1^2=\beta_1\]in this post. It must not be replaced by \(\tilde\beta_1=0\), which belongs to the degenerate clean-conditioned posterior rather than this observation likelihood.
The exact \(J_1\) involves logarithms of bin probabilities, so it is not exactly a quadratic reconstruction loss.
For an interior bin of width \(\Delta=2/255\), a small-bin approximation gives
\[\int_{x_0^i-\Delta/2}^{x_0^i+\Delta/2}f(r)\,dr \approx f(x_0^i)\Delta.\]Applying this to the Gaussian decoder gives
\[J_1(x_0) \approx \frac1{2\sigma_1^2} \mathbb{E}_{q(x_1\mid x_0)} \left[ \lVert x_0-\mu_\theta(x_1,1)\rVert^2 \right] +C_{\mathrm{dec}},\]where \(C_{\mathrm{dec}}\) is independent of \(\theta\). This approximation requires care at the boundary bins and when the density varies substantially within a bin.
At \(t=1\),
\[x_1 = \sqrt{\alpha_1}x_0+\sqrt{\beta_1}\epsilon,\]and Equation (11) gives
\[\mu_\theta(x_1,1)-x_0 = \sqrt{\frac{\beta_1}{\alpha_1}} \left( \epsilon-\epsilon_\theta(x_1,1) \right).\]Consequently,
\[\boxed{ J_1(x_0) \approx \frac{\beta_1}{2\sigma_1^2\alpha_1} \mathbb{E}_\epsilon \left[ \lVert\epsilon-\epsilon_\theta(x_1,1)\rVert^2 \right] +C_{\mathrm{dec}}. }\]With a continuous Gaussian observation likelihood, the corresponding squared-error relationship is exact up to a constant. For the discretized Gaussian likelihood, it uses the bin approximation described above. Appendix C.3-C.4 provides the details.
7.5 From the weighted bound to the simplified DDPM loss
Define the per-example noise error
\[\ell_t(\theta;x_0,\epsilon) := \left\lVert \epsilon- \epsilon_\theta\!\left( \sqrt{\bar\alpha_t}x_0+ \sqrt{1-\bar\alpha_t}\epsilon, t \right) \right\rVert^2.\]The exact bound has the form
\[\boxed{ \mathcal{L}_{\mathrm{bound}}(x_0) = C_{\mathrm{prior}}(x_0) + \sum_{t=2}^{T} \left( w_t\mathbb{E}_\epsilon[\ell_t]+C_t \right) + J_1(x_0). }\]Here, \(J_1\) still denotes the exact decoder likelihood term. Under our intermediate variance convention, all \(C_t\) in the sum are zero.
The commonly used DDPM objective instead applies unweighted noise prediction at every timestep:
\[\boxed{ \mathcal{L}_{\mathrm{simple}}(\theta) = \mathbb{E}_{\substack{ x_0\sim p_{\mathrm{data}}\\ t\sim\mathrm{Uniform}\{1,\ldots,T\}\\ \epsilon\sim\mathcal{N}(0,I) }} \left[ \lVert\epsilon-\epsilon_\theta(x_t,t)\rVert^2 \right], } \tag{13}\]where \(x_t\) is constructed using Equation (1). This is the simplified objective introduced in DDPM. The original paper reports that its reweighting improves sample quality in its experiments. (Ho et al., 2020, Section 3.4)
The distinction between the mathematical steps matters:
Operation Effect on optimization Remove additive terms independent of \(\theta\). Leaves gradients unchanged. Replace a sum over timesteps by its uniform average. Introduces a common factor \(1/T\), preserving minimizers. Replace timestep-dependent \(w_t\) by equal weights. Changes the relative importance of the denoising tasks. Replace the exact discrete reconstruction term by noise MSE at \(t=1\). Uses the decoder approximation and removes its scaling coefficient. In particular, a multiplicative coefficient cannot be discarded merely because it does not depend on \(\theta\):
\[\nabla_\theta\!\left(w_t\ell_t\right) = w_t\nabla_\theta\ell_t.\]When one network is shared across timesteps, changing their relative weights changes how their gradients are combined. The simplified loss is therefore not exactly the original negative ELBO or exact maximum likelihood.
It also does not remove the noise schedule from the model. The coefficients \(\alpha_t,\bar\alpha_t,\beta_t\) remain necessary for constructing noisy inputs and computing reverse means. The reverse variance remains prescribed; the unweighted noise loss does not learn an additional variance output.
The connection to the VAE calculation in Section 3.3 is direct. A fixed-variance Gaussian observation likelihood produces a squared reconstruction error. Here, a fixed-variance Gaussian conditional KL produces a squared mean error, which the noise parameterization converts into a squared noise error.
The resulting supervised task uses the current noisy image and timestep to predict the injected noise. Neither a sampled target \(x_{t-1}\) nor explicit numerical evaluation of a KL integral is required in the simplified training loop. The original implementation computes the noisy input and applies squared error directly to the noise prediction. (DDPM implementation)
Section 8 will use this loss to describe the training procedure and show how the trained network determines each reverse-sampling transition.
8. Training and Reverse Generation
Section 7 reduced the DDPM training objective to noise prediction. We now translate that objective into a training procedure and use the learned predictions to generate images.
The two procedures use the same network but perform different tasks:
During training, we corrupt known images and learn to predict the injected noise. During generation, we start from Gaussian noise and repeatedly sample learned reverse transitions.
We retain the conventions established earlier: the forward schedule is fixed, and the intermediate reverse variance is
\[\sigma_t^2=\tilde\beta_t = \frac{1-\bar\alpha_{t-1}}{1-\bar\alpha_t}\beta_t, \qquad t\geq2.\]The coefficients are determined by the schedule, not predicted by the network.
8.1 Training using randomly corrupted images
Use one shared network \(\epsilon_\theta(x_t,t)\) for every timestep. The timestep input identifies the noise level, allowing the same parameters to represent different denoising tasks. The original DDPM uses a timestep-conditioned U-Net with parameters shared across time. (Ho et al., 2020)
A training example is constructed by sampling
\[x_0\sim p_{\mathrm{data}}, \qquad t\sim\mathrm{Uniform}\{1,\ldots,T\}, \qquad \epsilon\sim\mathcal{N}(0,I).\]The selected timestep and noise are sampled independently of the clean image. Construct the noisy input using Equation (1):
\[x_t = \sqrt{\bar\alpha_t}x_0 + \sqrt{1-\bar\alpha_t}\epsilon.\]Then evaluate
\[\hat\epsilon=\epsilon_\theta(x_t,t).\]The supervised-learning pair is
\[\boxed{ \text{network input}=(x_t,t), \qquad \text{training target}=\epsilon. }\]The clean image determines how the input is constructed, but it is not separately supplied to the network. The target noise is known because we sampled it ourselves.
For a minibatch of \(B\) images, independently choose \(t_b\) and \(\epsilon^{(b)}\) for each image \(x_0^{(b)}\). The minibatch loss is
\[\boxed{ \widehat{\mathcal{L}}_{\mathrm{simple}} = \frac1B \sum_{b=1}^{B} \left\lVert \epsilon^{(b)} - \epsilon_\theta\!\left( x_{t_b}^{(b)},t_b \right) \right\rVert^2. }\]A gradient-descent update takes the form
\[\theta \leftarrow \theta-\gamma \nabla_\theta\widehat{\mathcal{L}}_{\mathrm{simple}},\]where \(\gamma\) is the learning rate. Only the network parameters are optimized; the forward schedule and prescribed reverse variances remain unchanged.
An implementation commonly averages the squared error over image coordinates as well as batch elements. For fixed image dimension \(D\), this introduces an additional factor \(1/D\), changing the loss scale but not its minimizers. The authors’ implementation uses such a mean-squared-error calculation. (DDPM training implementation)
Training procedure
Precompute the forward noise-schedule coefficients.

Repeat:
    Sample a minibatch of clean images x0.
    Sample one timestep t for each image.
    Draw Gaussian noise epsilon with the same shape as x0.

    xt = sqrt(alpha_bar[t]) * x0
        + sqrt(1 - alpha_bar[t]) * epsilon

    predicted_noise = noise_network(xt, t)
    loss = mean((epsilon - predicted_noise)^2)

    Backpropagate the loss and update the network parameters.
No explicit target \(x_{t-1}\), complete noisy trajectory, or reverse rollout is required in this loop. The derivations in Sections 6 and 7 have already transformed the local distribution-matching objective into a noise-prediction error.
Why sampling one timestep is sufficient
For a fixed clean image, define
\[g_t(x_0) = \mathbb{E}_\epsilon \left[ \left\lVert \epsilon-\epsilon_\theta(x_t,t) \right\rVert^2 \right].\]Uniform timestep sampling satisfies
\[\mathbb{E}_t[g_t(x_0)] = \frac1T\sum_{t=1}^{T}g_t(x_0).\]Thus, random-timestep training estimates the average over all denoising tasks. Across updates, the network encounters different images, noise realizations, and timesteps.
This is an estimate of the simplified objective in Equation (13). It does not reinstate the timestep-dependent weights or exact decoder likelihood discarded when moving away from the original negative ELBO.
There is also no requirement that the noisy inputs in a minibatch belong to one consistent Markov trajectory. Each input is a separate sample from the appropriate marginal \(q(x_t\mid x_0)\).
8.2 Generating images through learned reverse transitions
After training, fix the network parameters. Generation requires no clean image, training target, loss calculation, or gradient update.
Start by sampling an image-sized noise vector:
\[\boxed{x_T\sim\mathcal{N}(0,I).}\]Unlike a noisy training input, this initial state is sampled directly from the model prior. It is not constructed by corrupting a particular clean image.
For each intermediate timestep \(t=T,\ldots,2\), predict the noise and compute the reverse mean using Equation (11):
\[\mu_\theta(x_t,t) = \frac1{\sqrt{\alpha_t}} \left( x_t- \frac{\beta_t}{\sqrt{1-\bar\alpha_t}} \epsilon_\theta(x_t,t) \right).\]The learned transition is
\[p_\theta(x_{t-1}\mid x_t) = \mathcal{N}\!\left( x_{t-1};\mu_\theta(x_t,t),\sigma_t^2I \right).\]Sampling this Gaussian gives
\[\boxed{ \begin{aligned} x_{t-1} &= \frac1{\sqrt{\alpha_t}} \left( x_t- \frac{\beta_t}{\sqrt{1-\bar\alpha_t}} \epsilon_\theta(x_t,t) \right) + \sigma_t\xi_t,\\[4pt] &\hspace{2em}\xi_t\sim\mathcal{N}(0,I). \end{aligned} } \tag{14}\]Each \(\xi_t\) is a fresh draw, independent of the current state and previous random draws.
Under the variance convention used in this post,
\[\boxed{ \sigma_t = \sqrt{ \frac{1-\bar\alpha_{t-1}}{1-\bar\alpha_t}\beta_t }, \qquad t\geq2. }\]The square root is essential: \(\tilde\beta_t\) is a variance, whereas the sampling equation multiplies noise by its standard deviation. These coefficients can be precomputed and selected by timestep, as in the original implementation. (DDPM implementation)
The final step
At \(t=1\), the original DDPM sampling procedure returns the predicted mean without adding fresh noise. (Ho et al., 2020, Algorithm 2)
Since \(1-\bar\alpha_1=\beta_1\),
\[\boxed{ x_0^{\mathrm{gen}} = \mu_\theta(x_1,1) = \frac{ x_1-\sqrt{\beta_1}\epsilon_\theta(x_1,1) }{ \sqrt{\alpha_1} }. }\]This is the generated image.
Returning the mean is an output convention. It does not mean that the discretized Gaussian decoder in Section 7.4 has zero variance. That positive-variance likelihood defines how the observed pixels are scored during likelihood evaluation; displaying its underlying mean is a different operation.
Reverse-generation procedure
Fix the trained network parameters.
Precompute sigma[t] = sqrt(posterior_variance[t]) for t >= 2.

Sample x from a standard Gaussian.

For t = T, ..., 1:
    predicted_noise = noise_network(x, t)

    mean = (x - beta[t] / sqrt(1 - alpha_bar[t])
                * predicted_noise) / sqrt(alpha[t])

    If t > 1:
        Draw fresh standard Gaussian noise xi.
        x = mean + sigma[t] * xi
    Otherwise:
        x = mean

Return x.
This pseudocode uses the mathematical timestep convention \(t=1,\ldots,T\). Appendix D.2 explains the offset in zero-based implementations.
For the three-step illustration used in Appendix B, the procedure is
\[\begin{aligned} x_3&\sim\mathcal{N}(0,I),\\[4pt] x_2&=\mu_\theta(x_3,3)+\sqrt{\tilde\beta_3}\,\xi_3,\\[4pt] x_1&=\mu_\theta(x_2,2)+\sqrt{\tilde\beta_2}\,\xi_2,\\[4pt] x_0^{\mathrm{gen}}&=\mu_\theta(x_1,1). \end{aligned}\]This short chain illustrates the ordering, rather than proposing that three ordinary noise increments are sufficient for useful image generation. The schedule in Section 4 uses \(T=1000\), so the corresponding ancestral sampler performs 1000 sequential network evaluations for each generated image or batch. (Ho et al., 2020, Section 4)
8.3 Why the reverse sampler adds noise
The network determines the mean of the next reverse distribution. A mean is not, by itself, a sample from that distribution.
For a fixed current state \(x_t\), returning only
\[x_{t-1}=\mu_\theta(x_t,t)\]would give
\[\operatorname{Cov}(x_{t-1}\mid x_t)=0.\]By contrast, the chosen model specifies
\[\operatorname{Cov}(x_{t-1}\mid x_t)=\sigma_t^2I.\]The random residual in Equation (14) supplies that spread:
\[\begin{aligned} \mathbb{E}[x_{t-1}\mid x_t] &=\mu_\theta(x_t,t),\\[4pt] \operatorname{Cov}(x_{t-1}\mid x_t) &=\sigma_t^2I. \end{aligned}\]Thus, the predicted mean and the added noise perform different roles. The mean determines the center of the distribution of less-noisy states; the random term produces a sample around that center.
This does not mean that the network first reconstructs the exact clean image and then corrupts it again. At an intermediate timestep, it defines a distribution for the previous noisy state, not a complete deterministic reconstruction of \(x_0\).
The distinction between the noise symbols is:
Quantity Role \(\epsilon\) Known aggregate noise used to construct a training input. \(\epsilon_\theta(x_t,t)\) The network’s prediction of that noise. \(\xi_t\) Fresh randomness used to sample a learned reverse transition. \(x_T\) The initial image-sized sample from the generation prior. During generation, there is no known “correct injected noise” attached to the current state. The network evaluates the function learned during training, and its output parameterizes the next transition.
Removing every \(\xi_t\) while leaving the rest of Equation (14) unchanged would define a different conditional process. It would no longer sample the Gaussian transitions specified in Section 4. Appendix D, Section D.1, gives a concrete example showing why adding a random residual can still be consistent with moving toward a less-noisy distribution.
8.4 Completing the connection between VAE and DDPM
The training and generation procedures can now be separated clearly:
Training Generation Starting information Clean dataset images. Samples from the Gaussian prior. Source of the current noisy input Direct forward corruption. The preceding reverse-sampling step. Network evaluation At randomly selected timesteps. Sequentially from \(T\) to \(1\). Target and loss Known noise and a prediction loss. No target or loss. Network parameters Updated by backpropagation. Held fixed. As with the VAE in Part I, the inference mechanism used during training is not required to generate a new image. A VAE samples its prior and evaluates its decoder; the encoder is unnecessary for this unconditional generation step. (Kingma and Welling, 2013)
DDPM replaces that single decoding stage with a hierarchy of learned transitions. Its fixed forward process supplies tractable training distributions, while the trained network is repeatedly evaluated to generate the latent path in reverse.
The full development is therefore
\[\boxed{ \begin{gathered} \text{Latent-variable generative model}\\[3pt] \Downarrow\\[3pt] \text{Variational likelihood bound}\\[3pt] \Downarrow\\[3pt] \text{Local Gaussian distribution matching}\\[3pt] \Downarrow\\[3pt] \text{Noise-prediction training}\\[3pt] \Downarrow\\[3pt] \text{Sequential reverse generation}. \end{gathered} }\]The probabilistic derivation explains the role of the training target and the sampling rule. The implementation then becomes two distinct loops: learn from randomly corrupted images, and generate by repeatedly applying the learned reverse transitions.
DDPM Results
Appendix A. Conditional Bayes’ Rule and the Gaussian Reverse Posterior
This appendix derives the target distribution in Section 5.3. The calculation uses only the specified forward process; no neural-network approximation is involved.
A.1 Identify the unknown variable
Fix an intermediate timestep \(t\geq2\), and write
\[y=x_{t-1}.\]In the following calculation, \(x_0\) and \(x_t\) are known and held fixed. The variable \(y\in\mathbb{R}^D\) is the unknown whose conditional density we seek.
The forward process gives
\[q(y\mid x_0) = \mathcal{N}\!\left( y;\sqrt{\bar\alpha_{t-1}}x_0, (1-\bar\alpha_{t-1})I \right)\]and
\[q(x_t\mid y) = \mathcal{N}\!\left( x_t;\sqrt{\alpha_t}y,\beta_t I \right).\]The first density describes plausible previous states given the clean origin. The second evaluates how compatible each candidate previous state is with the observed next state.
A.2 Derive conditional Bayes’ rule
The conditional joint density \(q(y,x_t\mid x_0)\) can be factored in two ways:
\[q(y,x_t\mid x_0) = q(y\mid x_t,x_0)\,q(x_t\mid x_0)\]and
\[q(y,x_t\mid x_0) = q(x_t\mid y,x_0)\,q(y\mid x_0).\]Equating the two expressions and dividing by \(q(x_t\mid x_0)\) gives
\[q(y\mid x_t,x_0) = \frac{ q(x_t\mid y,x_0)\,q(y\mid x_0) }{ q(x_t\mid x_0) }.\]This is conditional Bayes’ rule: ordinary Bayes’ rule with the additional background information \(x_0\) retained throughout. No independence assumption was used to obtain this identity.
The forward Markov property gives
\[q(x_t\mid y,x_0)=q(x_t\mid y),\]so
\[\boxed{ q(y\mid x_t,x_0) = \frac{ q(x_t\mid y)\,q(y\mid x_0) }{ q(x_t\mid x_0) }. } \tag{A.1}\]This Markov simplification does not remove \(x_0\) from the posterior on the left-hand side. Knowing the clean origin still provides information about the missing previous state.
Because \(x_t,x_0\) are fixed, the denominator is constant with respect to \(y\). Therefore,
\[\boxed{ q(y\mid x_t,x_0) \propto q(x_t\mid y)\,q(y\mid x_0). } \tag{A.2}\]The symbol \(\propto\) means equality up to a multiplicative factor independent of \(y\), not approximate equality.
The denominator supplies the normalization:
\[q(x_t\mid x_0) = \int q(x_t\mid y)q(y\mid x_0)\,dy.\]Dividing by this quantity ensures that the posterior integrates to one.
A.3 Substitute the Gaussian densities
An isotropic Gaussian density in \(D\) dimensions has the form
\[\mathcal{N}(r;m,vI) = \frac{1}{(2\pi v)^{D/2}} \exp\!\left[ -\frac{\lVert r-m\rVert^2}{2v} \right].\]Here, \(v\) is the variance coefficient, so the covariance matrix is \(vI\).
Thus,
\[q(x_t\mid y) = \frac{1}{(2\pi\beta_t)^{D/2}} \exp\!\left[ -\frac{\lVert x_t-\sqrt{\alpha_t}y\rVert^2}{2\beta_t} \right]\]and
\[\begin{aligned} q(y\mid x_0) ={}& \frac{1}{[2\pi(1-\bar\alpha_{t-1})]^{D/2}}\\[4pt] &\times \exp\!\left[ -\frac{\lVert y-\sqrt{\bar\alpha_{t-1}}x_0\rVert^2} {2(1-\bar\alpha_{t-1})} \right]. \end{aligned}\]Substituting these expressions into Equation (A.1) produces a product of two exponentials. Using \(e^a e^b=e^{a+b}\),
\[\boxed{ \begin{aligned} &q(y\mid x_t,x_0)\\[4pt] &=K\exp\!\left[ -\frac12 \left( \frac{\lVert x_t-\sqrt{\alpha_t}y\rVert^2}{\beta_t} + \frac{\lVert y-\sqrt{\bar\alpha_{t-1}}x_0\rVert^2} {1-\bar\alpha_{t-1}} \right) \right], \end{aligned} } \tag{A.3}\]where
\[K= \frac{ 1 }{ q(x_t\mid x_0) (2\pi\beta_t)^{D/2} [2\pi(1-\bar\alpha_{t-1})]^{D/2} }\]does not depend on \(y\).
This explains the exponential expression: it comes directly from multiplying the Gaussian densities in Bayes’ rule. Writing \(\propto\) instead of equality allows us to suppress the multiplicative constant \(K\) while retaining the density’s dependence on \(y\).
A.4 Collect the quadratic terms
Expand the first squared norm:
\[\lVert x_t-\sqrt{\alpha_t}y\rVert^2 = \lVert x_t\rVert^2 -2\sqrt{\alpha_t}\,x_t^\top y +\alpha_t\lVert y\rVert^2.\]Expand the second:
\[\begin{aligned} \lVert y-\sqrt{\bar\alpha_{t-1}}x_0\rVert^2 ={}& \lVert y\rVert^2 -2\sqrt{\bar\alpha_{t-1}}\,x_0^\top y\\[4pt] &+ \bar\alpha_{t-1}\lVert x_0\rVert^2. \end{aligned}\]After division by the respective variances and collection of like terms,
\[\begin{aligned} & \frac{\lVert x_t-\sqrt{\alpha_t}y\rVert^2}{\beta_t} + \frac{\lVert y-\sqrt{\bar\alpha_{t-1}}x_0\rVert^2} {1-\bar\alpha_{t-1}}\\[4pt] &\qquad= A\lVert y\rVert^2-2h^\top y+C, \end{aligned}\]where
\[A= \frac{\alpha_t}{\beta_t} + \frac{1}{1-\bar\alpha_{t-1}},\] \[h= \frac{\sqrt{\alpha_t}}{\beta_t}x_t + \frac{\sqrt{\bar\alpha_{t-1}}} {1-\bar\alpha_{t-1}}x_0,\]and
\[C= \frac{\lVert x_t\rVert^2}{\beta_t} + \frac{\bar\alpha_{t-1}\lVert x_0\rVert^2} {1-\bar\alpha_{t-1}}.\]The quantity \(A\) is a positive scalar, \(h\) is a vector, and \(C\) is independent of \(y\). Hence,
\[q(y\mid x_t,x_0) \propto \exp\!\left[ -\frac12\left(A\lVert y\rVert^2-2h^\top y+C\right) \right].\]A.5 Complete the square and identify the Gaussian
A Gaussian density is recognizable from an exponent of the form
\[-\frac{1}{2v}\lVert y-m\rVert^2.\]Completing the square rewrites our quadratic in precisely this form.
Expand
\[A\left\lVert y-\frac hA\right\rVert^2 = A\lVert y\rVert^2-2h^\top y+\frac{\lVert h\rVert^2}{A}.\]Rearranging,
\[\boxed{ A\lVert y\rVert^2-2h^\top y+C = A\left\lVert y-\frac hA\right\rVert^2 + C-\frac{\lVert h\rVert^2}{A}. }\]Therefore,
\[\begin{aligned} q(y\mid x_t,x_0) \propto{}& \underbrace{ \exp\!\left[ -\frac12\left(C-\frac{\lVert h\rVert^2}{A}\right) \right] }_{\text{independent of }y}\\[4pt] &\times \exp\!\left[ -\frac A2\left\lVert y-\frac hA\right\rVert^2 \right]. \end{aligned}\]The first factor can be absorbed into the normalization constant:
\[q(y\mid x_t,x_0) \propto \exp\!\left[ -\frac A2\left\lVert y-\frac hA\right\rVert^2 \right].\]Comparing the center of the square and its coefficient with the standard Gaussian form gives
\[\boxed{ \tilde\mu_t=\frac hA, \qquad \tilde\beta_t=\frac1A. }\]In particular, \(1/A\) is the variance coefficient; the standard deviation in each coordinate is \(1/\sqrt A\).
Restoring normalization,
\[q(y\mid x_t,x_0) = \left(\frac{A}{2\pi}\right)^{D/2} \exp\!\left[ -\frac A2\left\lVert y-\frac hA\right\rVert^2 \right].\]Thus, the posterior is exactly Gaussian under the chosen forward model. Completing the square has not changed or approximated the density. It has exposed its center and covariance.
A.6 Recover the final mean and variance
First simplify \(A\):
\[\begin{aligned} A &= \frac{ \alpha_t(1-\bar\alpha_{t-1})+\beta_t }{ \beta_t(1-\bar\alpha_{t-1}) }\\[4pt] &= \frac{ \alpha_t+\beta_t-\alpha_t\bar\alpha_{t-1} }{ \beta_t(1-\bar\alpha_{t-1}) }\\[4pt] &= \frac{1-\bar\alpha_t} {\beta_t(1-\bar\alpha_{t-1})}. \end{aligned}\]The last equality uses
\[\alpha_t+\beta_t=1, \qquad \bar\alpha_t=\alpha_t\bar\alpha_{t-1}.\]Taking the reciprocal gives
\[\boxed{ \tilde\beta_t = \frac{1-\bar\alpha_{t-1}}{1-\bar\alpha_t}\beta_t, }\]which is Equation (4).
Next,
\[\begin{aligned} \tilde\mu_t = \frac hA ={}& \left( \frac{\sqrt{\alpha_t}}{\beta_t}x_t + \frac{\sqrt{\bar\alpha_{t-1}}} {1-\bar\alpha_{t-1}}x_0 \right)\\[4pt] &\times \frac{\beta_t(1-\bar\alpha_{t-1})} {1-\bar\alpha_t}. \end{aligned}\]Distributing the factor gives
\[\boxed{ \tilde\mu_t(x_t,x_0) = \frac{\sqrt{\alpha_t}(1-\bar\alpha_{t-1})} {1-\bar\alpha_t}x_t + \frac{\sqrt{\bar\alpha_{t-1}}\beta_t} {1-\bar\alpha_t}x_0, }\]which is Equation (3).
The restriction \(t\geq2\) avoids the degenerate case \(1-\bar\alpha_0=0\). At \(t=1\), conditioning on \(x_0\) makes the corresponding distribution over \(x_0\) a point mass; the final reconstruction likelihood is therefore treated separately.
The calculation derives a posterior inside the known forward process. Choosing the learned reverse model to be Gaussian, and choosing its variance to equal this posterior variance, are separate modeling decisions.
Appendix B. Reverse-Order Factorization and the ELBO Decomposition
Appendix A derives the Gaussian posterior parameters. This appendix explains a different part of the argument: how the full-path expectation in Equation (5) becomes the local terms in Equation (8).
The calculations below use conditional factorization, marginalization, and the definition of KL divergence. They do not require expanding any Gaussian density.
B.1 Rewriting the forward path in reverse order
Conditional Bayes’ rule from Appendix A gives
\[q(x_{t-1}\mid x_t,x_0) = q(x_t\mid x_{t-1}) \frac{q(x_{t-1}\mid x_0)}{q(x_t\mid x_0)}.\]Multiply this identity over \(t=2,\ldots,T\):
\[\begin{aligned} \prod_{t=2}^{T}q(x_{t-1}\mid x_t,x_0) ={}& \left[ \prod_{t=2}^{T}q(x_t\mid x_{t-1}) \right]\\[4pt] &\times \left[ \prod_{t=2}^{T} \frac{q(x_{t-1}\mid x_0)}{q(x_t\mid x_0)} \right]. \end{aligned}\]The second product expands to
\[\frac{q(x_1\mid x_0)}{q(x_2\mid x_0)} \frac{q(x_2\mid x_0)}{q(x_3\mid x_0)} \cdots \frac{q(x_{T-1}\mid x_0)}{q(x_T\mid x_0)}.\]Every intermediate factor appears once in the numerator and once in the denominator. Therefore,
\[\prod_{t=2}^{T} \frac{q(x_{t-1}\mid x_0)}{q(x_t\mid x_0)} = \frac{q(x_1\mid x_0)}{q(x_T\mid x_0)}.\]This telescoping cancellation is ordinary algebra. It cancels identical density factors, not latent variables.
Consequently,
\[\begin{aligned} \prod_{t=2}^{T}q(x_{t-1}\mid x_t,x_0) &= \frac{ q(x_1\mid x_0) \prod_{t=2}^{T}q(x_t\mid x_{t-1}) }{ q(x_T\mid x_0) }\\[4pt] &= \frac{q(x_{1:T}\mid x_0)}{q(x_T\mid x_0)}. \end{aligned}\]Multiplying by \(q(x_T\mid x_0)\) gives
\[\boxed{ q(x_{1:T}\mid x_0) = q(x_T\mid x_0) \prod_{t=2}^{T}q(x_{t-1}\mid x_t,x_0), }\]which is Equation (6).
B.2 Expand the negative ELBO for three steps
Let \(T=3\), so the forward chain has three transitions:
\[x_0\rightarrow x_1\rightarrow x_2\rightarrow x_3.\]Keep \(x_0\) fixed, and abbreviate the forward-path density as
\[Q(x_1,x_2,x_3) := q(x_1,x_2,x_3\mid x_0).\]The capital \(Q\) is only shorthand for this density with \(x_0\) fixed; it does not denote a new probability model. It has two equivalent factorizations:
\[\begin{aligned} Q(x_1,x_2,x_3) &= q(x_1\mid x_0)q(x_2\mid x_1)q(x_3\mid x_2)\\[4pt] &= q(x_3\mid x_0)q(x_2\mid x_3,x_0)q(x_1\mid x_2,x_0). \end{aligned}\]The generative joint density is
\[p_\theta(x_0,x_1,x_2,x_3) = p(x_3) p_\theta(x_2\mid x_3) p_\theta(x_1\mid x_2) p_\theta(x_0\mid x_1).\]Substituting these expressions into the negative ELBO and splitting the logarithm gives
\[\begin{aligned} \mathcal{L}_{\mathrm{bound}}(x_0) ={}& \mathbb{E}_Q \left[ \log\frac{q(x_3\mid x_0)}{p(x_3)} \right] \\[4pt] &+ \mathbb{E}_Q \left[ \log\frac{q(x_2\mid x_3,x_0)} {p_\theta(x_2\mid x_3)} \right] \\[4pt] &+ \mathbb{E}_Q \left[ \log\frac{q(x_1\mid x_2,x_0)} {p_\theta(x_1\mid x_2)} \right] \\[4pt] &- \mathbb{E}_Q [\log p_\theta(x_0\mid x_1)]. \end{aligned} \tag{B.1}\]Each expectation initially integrates over all three latent states:
\[\mathbb{E}_Q[f] = \iiint Q(x_1,x_2,x_3)f(x_1,x_2,x_3) \,dx_1\,dx_2\,dx_3.\]The next step is to remove integration variables that do not appear in the particular function being averaged.
B.3 Evaluate the four expectations
The terminal-prior term
The first log ratio depends only on \(x_3\). Marginalizing the other states gives
\[\iint Q(x_1,x_2,x_3)\,dx_1\,dx_2 = q(x_3\mid x_0).\]Therefore,
\[\begin{aligned} &\mathbb{E}_Q \left[ \log\frac{q(x_3\mid x_0)}{p(x_3)} \right]\\[4pt] &= \int q(x_3\mid x_0) \log\frac{q(x_3\mid x_0)}{p(x_3)} \,dx_3\\[4pt] &= D_{\mathrm{KL}}\!\left( q(x_3\mid x_0)\,\Vert\,p(x_3) \right). \end{aligned}\]The KL already integrates over \(x_3\), so no additional expectation over \(x_3\) remains.
The reverse transition \(x_3\rightarrow x_2\)
The second log ratio depends on \(x_2,x_3\), but not on \(x_1\). Using the reverse-order factorization,
\[\begin{aligned} \int Q(x_1,x_2,x_3)\,dx_1 ={}& q(x_3\mid x_0)q(x_2\mid x_3,x_0)\\[4pt] &\times \underbrace{ \int q(x_1\mid x_2,x_0)\,dx_1 }_{1}. \end{aligned}\]The remaining expectation is
\[\begin{aligned} &\mathbb{E}_Q \left[ \log\frac{q(x_2\mid x_3,x_0)} {p_\theta(x_2\mid x_3)} \right]\\[4pt] &= \int q(x_3\mid x_0) \left[ \int q(x_2\mid x_3,x_0) \log \frac{q(x_2\mid x_3,x_0)} {p_\theta(x_2\mid x_3)} \,dx_2 \right]dx_3\\[4pt] &= \mathbb{E}_{q(x_3\mid x_0)} \left[ D_{\mathrm{KL}}\!\left( q(x_2\mid x_3,x_0) \,\Vert\, p_\theta(x_2\mid x_3) \right) \right]. \end{aligned}\]The inner KL integrates over \(x_2\), holding \(x_3\) fixed. The outer expectation then averages that conditional comparison over possible \(x_3\).
The reverse transition \(x_2\rightarrow x_1\)
The third log ratio depends on \(x_1,x_2\), but not on \(x_3\). This time, the forward factorization makes marginalization convenient:
\[\begin{aligned} \int Q(x_1,x_2,x_3)\,dx_3 &= q(x_1\mid x_0)q(x_2\mid x_1) \underbrace{ \int q(x_3\mid x_2)\,dx_3 }_{1}\\[4pt] &= q(x_1,x_2\mid x_0). \end{aligned}\]Factor the two-state marginal in the other direction:
\[q(x_1,x_2\mid x_0) = q(x_2\mid x_0)q(x_1\mid x_2,x_0).\]Hence,
\[\begin{aligned} &\mathbb{E}_Q \left[ \log\frac{q(x_1\mid x_2,x_0)} {p_\theta(x_1\mid x_2)} \right]\\[4pt] &= \int q(x_2\mid x_0) \left[ \int q(x_1\mid x_2,x_0) \log \frac{q(x_1\mid x_2,x_0)} {p_\theta(x_1\mid x_2)} \,dx_1 \right]dx_2\\[4pt] &= \mathbb{E}_{q(x_2\mid x_0)} \left[ D_{\mathrm{KL}}\!\left( q(x_1\mid x_2,x_0) \,\Vert\, p_\theta(x_1\mid x_2) \right) \right]. \end{aligned}\]This calculation illustrates the distinction between the two operations:
Marginalization removes \(x_3\) by integration. Conditional factorization rewrites the remaining joint density without removing any additional variable.
In general,
\[\int q(a\mid b)\,da=1,\]because the integration is over the variable whose conditional distribution is specified. Integrating over the conditioning variable \(b\) would not generally produce one.
The final reconstruction term
For fixed \(x_0\), the final log-likelihood depends only on \(x_1\). The forward factorization gives
\[\begin{aligned} &\iint Q(x_1,x_2,x_3)\,dx_3\,dx_2\\[4pt] &= q(x_1\mid x_0) \int q(x_2\mid x_1) \underbrace{ \left[ \int q(x_3\mid x_2)\,dx_3 \right] }_{1} dx_2\\[4pt] &= q(x_1\mid x_0). \end{aligned}\]Therefore,
\[\begin{aligned} -\mathbb{E}_Q[\log p_\theta(x_0\mid x_1)] &= -\int q(x_1\mid x_0) \log p_\theta(x_0\mid x_1)\,dx_1\\[4pt] &= -\mathbb{E}_{q(x_1\mid x_0)} [\log p_\theta(x_0\mid x_1)]. \end{aligned}\]This evaluates the likelihood of the observed clean image and averages over its possible first-step corruptions. The observation itself remains fixed.
B.4 Reassemble the global objective
Substituting the four results into Equation (B.1),
\[\boxed{ \begin{aligned} \mathcal{L}_{\mathrm{bound}}(x_0) ={}& D_{\mathrm{KL}}\!\left( q(x_3\mid x_0)\,\Vert\,p(x_3) \right) \\[4pt] &+ \mathbb{E}_{q(x_3\mid x_0)} \left[ D_{\mathrm{KL}}\!\left( q(x_2\mid x_3,x_0) \,\Vert\, p_\theta(x_2\mid x_3) \right) \right] \\[4pt] &+ \mathbb{E}_{q(x_2\mid x_0)} \left[ D_{\mathrm{KL}}\!\left( q(x_1\mid x_2,x_0) \,\Vert\, p_\theta(x_1\mid x_2) \right) \right] \\[4pt] &- \mathbb{E}_{q(x_1\mid x_0)} [\log p_\theta(x_0\mid x_1)]. \end{aligned} }\]This is Equation (8) with \(T=3\).
For an arbitrary intermediate timestep, the same procedure integrates out
\[x_1,\ldots,x_{t-2}, \qquad x_{t+1},\ldots,x_T,\]leaving the pair \(x_{t-1},x_t\). The inner KL integrates over \(x_{t-1}\), and the outer expectation integrates over \(x_t\).
Throughout this derivation, \(x_0\) is fixed. Averaging over different training images is the separate dataset-level operation applied to \(\mathcal{L}_{\mathrm{bound}}(x_0)\).
The bound is global in what it measures, the image likelihood, but local in how it decomposes. The decomposition exposes tractable training terms without changing the original variational objective.
Appendix C. Gaussian KL, Noise Parameterization, and the Reconstruction Term
Appendix A derived the target posterior’s parameters, and Appendix B derived the local loss decomposition. This appendix supplies the calculations that connect those results to the practical noise-prediction objective.
C.1 Deriving the Gaussian KL as a mean-prediction error
Fix \(x_0,x_t\), and a timestep \(t\geq2\). Write
\[y=x_{t-1}, \qquad m_q=\tilde\mu_t(x_t,x_0), \qquad m_p=\mu_\theta(x_t,t).\]For this calculation, abbreviate
\[q_y(y):=q(y\mid x_t,x_0), \qquad p_y(y):=p_\theta(y\mid x_t).\]These are normalized densities over \(y\):
\[q_y(y) = \frac1{(2\pi\tilde\beta_t)^{D/2}} \exp\!\left( -\frac{\lVert y-m_q\rVert^2}{2\tilde\beta_t} \right),\] \[p_y(y) = \frac1{(2\pi\sigma_t^2)^{D/2}} \exp\!\left( -\frac{\lVert y-m_p\rVert^2}{2\sigma_t^2} \right).\]Taking logarithms and subtracting,
\[\boxed{ \log\frac{q_y(y)}{p_y(y)} = \frac D2\log\frac{\sigma_t^2}{\tilde\beta_t} - \frac{\lVert y-m_q\rVert^2}{2\tilde\beta_t} + \frac{\lVert y-m_p\rVert^2}{2\sigma_t^2}. } \tag{C.1}\]This is the Gaussian log-density ratio. It becomes a KL divergence only after taking its expectation under \(q_y\).
Under this target distribution,
\[\mathbb{E}_{q_y}[y]=m_q, \qquad \operatorname{Cov}_{q_y}(y)=\tilde\beta_t I.\]Therefore,
\[\begin{aligned} \mathbb{E}_{q_y}[\lVert y-m_q\rVert^2] &= \sum_{i=1}^{D} \mathbb{E}_{q_y}[(y_i-m_{q,i})^2]\\[4pt] &= D\tilde\beta_t. \end{aligned}\]To calculate the distance from the predicted mean, write
\[y-m_p=(y-m_q)+(m_q-m_p).\]Expanding,
\[\begin{aligned} \lVert y-m_p\rVert^2 ={}& \lVert y-m_q\rVert^2 + 2(y-m_q)^\top(m_q-m_p)\\[4pt] &+ \lVert m_q-m_p\rVert^2. \end{aligned}\]The expectation of the cross term is zero because
\[\mathbb{E}_{q_y}[y-m_q]=0.\]Hence,
\[\mathbb{E}_{q_y}[\lVert y-m_p\rVert^2] = D\tilde\beta_t+\lVert m_q-m_p\rVert^2.\]Taking the expectation of Equation (C.1),
\[\begin{aligned} D_{\mathrm{KL}}(q_y\Vert p_y) &= \frac D2\log\frac{\sigma_t^2}{\tilde\beta_t} - \frac{D\tilde\beta_t}{2\tilde\beta_t} + \frac{D\tilde\beta_t+\lVert m_q-m_p\rVert^2} {2\sigma_t^2}\\[4pt] &= \frac{\lVert m_q-m_p\rVert^2}{2\sigma_t^2} + \frac D2 \left[ \frac{\tilde\beta_t}{\sigma_t^2} -1+ \log\frac{\sigma_t^2}{\tilde\beta_t} \right]. \end{aligned}\]This is Equation (9).
The additional covariance contribution is independent of \(\theta\) only because the variances are prescribed. If the model variance were learned, its terms would need to remain in the optimization objective.
C.2 Converting the posterior mean into the noise parameterization
Begin with the posterior mean from Equation (3):
\[\tilde\mu_t(x_t,x_0) = \frac{\sqrt{\alpha_t}(1-\bar\alpha_{t-1})} {1-\bar\alpha_t}x_t + \frac{\sqrt{\bar\alpha_{t-1}}\beta_t} {1-\bar\alpha_t}x_0.\]The forward sample satisfies
\[x_t = \sqrt{\bar\alpha_t}x_0+ \sqrt{1-\bar\alpha_t}\epsilon,\]so
\[x_0 = \frac{x_t-\sqrt{1-\bar\alpha_t}\epsilon} {\sqrt{\bar\alpha_t}}.\]Substitute this into the posterior mean:
\[\begin{aligned} \tilde\mu_t ={}& \frac{\sqrt{\alpha_t}(1-\bar\alpha_{t-1})} {1-\bar\alpha_t}x_t\\[4pt] &+ \frac{\sqrt{\bar\alpha_{t-1}}\beta_t} {1-\bar\alpha_t} \frac{x_t-\sqrt{1-\bar\alpha_t}\epsilon} {\sqrt{\bar\alpha_t}}. \end{aligned}\]Since
\[\bar\alpha_t=\alpha_t\bar\alpha_{t-1},\]we have
\[\frac{\sqrt{\bar\alpha_{t-1}}}{\sqrt{\bar\alpha_t}} = \frac1{\sqrt{\alpha_t}}.\]Therefore,
\[\begin{aligned} \tilde\mu_t ={}& \frac{ \alpha_t(1-\bar\alpha_{t-1})+\beta_t }{ \sqrt{\alpha_t}(1-\bar\alpha_t) }x_t\\[4pt] &- \frac{\beta_t} {\sqrt{\alpha_t}\sqrt{1-\bar\alpha_t}}\epsilon. \end{aligned}\]The numerator in the first coefficient simplifies as
\[\begin{aligned} \alpha_t(1-\bar\alpha_{t-1})+\beta_t &= \alpha_t+\beta_t-\alpha_t\bar\alpha_{t-1}\\[4pt] &= 1-\bar\alpha_t. \end{aligned}\]Consequently,
\[\boxed{ \tilde\mu_t(x_t,x_0) = \frac1{\sqrt{\alpha_t}} \left( x_t- \frac{\beta_t}{\sqrt{1-\bar\alpha_t}}\epsilon \right), }\]which is Equation (10).
Define \(\mu_\theta\) by replacing \(\epsilon\) with \(\epsilon_\theta(x_t,t)\). Their difference is
\[\tilde\mu_t-\mu_\theta = \frac{\beta_t} {\sqrt{\alpha_t}\sqrt{1-\bar\alpha_t}} \left(\epsilon_\theta(x_t,t)-\epsilon\right).\]Substitution into Equation (9) yields the coefficient
\[w_t = \frac{\beta_t^2} {2\sigma_t^2\alpha_t(1-\bar\alpha_t)}.\]Under \(\sigma_t^2=\tilde\beta_t\),
\[\begin{aligned} w_t &= \frac{\beta_t^2}{ 2 \left[ \frac{1-\bar\alpha_{t-1}}{1-\bar\alpha_t}\beta_t \right] \alpha_t(1-\bar\alpha_t) }\\[4pt] &= \boxed{ \frac{\beta_t} {2\alpha_t(1-\bar\alpha_{t-1})} }. \end{aligned}\]This derivation applies to \(t\geq2\). Substituting \(t=1\) into this last expression would divide by \(1-\bar\alpha_0=0\), which is another reason to treat the observation likelihood separately.
C.3 The exact discretized Gaussian decoder
An 8-bit pixel \(k\in\{0,\ldots,255\}\), scaled to \([-1,1]\), takes the value
\[v=-1+\frac{2k}{255}.\]Neighboring values are separated by
\[\Delta=\frac2{255}.\]A continuous Gaussian assigns probability through areas under its density, rather than through the density value at an isolated point. To obtain a probability mass for the observed discrete pixel, integrate over the interval that rounds to that pixel.
Define
\[b^-(v) = \begin{cases} -\infty,&v=-1,\\[4pt] v-\Delta/2,&v>-1, \end{cases}\]and
\[b^+(v) = \begin{cases} +\infty,&v=1,\\[4pt] v+\Delta/2,&v<1. \end{cases}\]The extreme bins include the Gaussian tails, ensuring that the probabilities across all allowed pixel values sum to one.
For coordinate \(i\), let
\[m_i=\mu_\theta^i(x_1,1).\]The decoder is
\[\boxed{ p_\theta(x_0\mid x_1) = \prod_{i=1}^{D} \int_{b^-(x_0^i)}^{b^+(x_0^i)} \mathcal{N}(r;m_i,\sigma_1^2)\,dr. } \tag{C.2}\]This is the discretized Gaussian observation model used in DDPM, with a separately prescribed positive decoder variance. (Ho et al., 2020, Section 3.3)
Using the standard normal cumulative distribution function \(\Phi\), each factor is
\[\Phi\left( \frac{b^+(x_0^i)-m_i}{\sigma_1} \right) - \Phi\left( \frac{b^-(x_0^i)-m_i}{\sigma_1} \right).\]Therefore, the exact reconstruction term is
\[\boxed{ \begin{aligned} J_1(x_0) = -\mathbb{E}_{q(x_1\mid x_0)} \Bigg[ \sum_{i=1}^{D} \log\Bigg( & \Phi\left( \frac{b^+(x_0^i)-m_i}{\sigma_1} \right)\\[-2pt] &- \Phi\left( \frac{b^-(x_0^i)-m_i}{\sigma_1} \right) \Bigg) \Bigg]. \end{aligned} }\]The network supplies the predicted means \(m_i\). The observed image supplies the bin boundaries at which that predicted distribution is evaluated. These are distinct roles.
This exact expression is not a squared-error loss.
C.4 Approximating the reconstruction term by noise error
For an interior bin, when a density \(f\) varies little across its width,
\[\int_{v-\Delta/2}^{v+\Delta/2}f(r)\,dr \approx f(v)\Delta.\]Apply this to Equation (C.2), temporarily ignoring the boundary-bin effects:
\[p_\theta(x_0\mid x_1) \approx \prod_{i=1}^{D} \left[ \mathcal{N}(x_0^i;m_i,\sigma_1^2)\Delta \right].\]Taking the negative logarithm,
\[\begin{aligned} -\log p_\theta(x_0\mid x_1) &\approx -\sum_{i=1}^{D} \log\mathcal{N}(x_0^i;m_i,\sigma_1^2) -D\log\Delta\\[4pt] &= \frac{ \lVert x_0-\mu_\theta(x_1,1)\rVert^2 }{ 2\sigma_1^2 } + C_{\mathrm{dec}}, \end{aligned}\]where
\[C_{\mathrm{dec}} = \frac D2\log(2\pi\sigma_1^2)-D\log\Delta.\]The constant does not depend on the network parameters.
Now use
\[x_1=\sqrt{\alpha_1}x_0+\sqrt{\beta_1}\epsilon.\]Since \(1-\bar\alpha_1=\beta_1\), Equation (11) at \(t=1\) becomes
\[\mu_\theta(x_1,1) = \frac1{\sqrt{\alpha_1}} \left( x_1-\sqrt{\beta_1}\epsilon_\theta(x_1,1) \right).\]Substituting the forward expression for \(x_1\),
\[\begin{aligned} \mu_\theta(x_1,1) &= \frac{ \sqrt{\alpha_1}x_0 + \sqrt{\beta_1}\epsilon - \sqrt{\beta_1}\epsilon_\theta(x_1,1) }{ \sqrt{\alpha_1} }\\[4pt] &= x_0+ \sqrt{\frac{\beta_1}{\alpha_1}} \left( \epsilon-\epsilon_\theta(x_1,1) \right). \end{aligned}\]Hence,
\[\lVert x_0-\mu_\theta(x_1,1)\rVert^2 = \frac{\beta_1}{\alpha_1} \lVert\epsilon-\epsilon_\theta(x_1,1)\rVert^2.\]Averaging over the sampled noise gives
\[\boxed{ J_1(x_0) \approx w_1\, \mathbb{E}_\epsilon \left[ \lVert\epsilon-\epsilon_\theta(x_1,1)\rVert^2 \right] + C_{\mathrm{dec}}, }\]with
\[w_1 = \frac{\beta_1}{2\sigma_1^2\alpha_1}.\]For the decoder choice \(\sigma_1^2=\beta_1\),
\[w_1=\frac1{2\alpha_1}.\]If a continuous Gaussian likelihood were used instead, the squared reconstruction error would follow exactly from its negative log-density, with constant \(\frac D2\log(2\pi\sigma_1^2)\) and no bin-width term. This is the same likelihood-to-squared-error relationship discussed for VAE in Section 3.3. (Kingma and Welling, 2013)
For the discrete-pixel model, the steps must remain distinct:
\[\boxed{ \begin{gathered} \text{Exact discrete reconstruction likelihood}\\[4pt] \Downarrow\ \text{approximate bin probabilities}\\[4pt] \text{Weighted clean-image squared error}\\[4pt] \Downarrow\ \text{exact noise reparameterization}\\[4pt] \text{Weighted noise-prediction error}\\[4pt] \Downarrow\ \text{change the loss weighting}\\[4pt] \text{Unweighted noise-prediction error}. \end{gathered} }\]The intermediate Gaussian KL calculations are exact. The final decoder approximation and the removal of timestep-dependent weights are separate changes introduced when moving to the simplified training objective.
Appendix D. Reverse-Sampling Randomness and Implementation Conventions
The main derivations are complete in Appendices A-C. This appendix addresses the remaining distinction between a conditional mean and a sample, together with two implementation conventions that can otherwise obscure the equations.
D.1 A reverse step can add noise while reducing overall corruption
Consider a scalar example using the same forward-process form as DDPM. Let
\[x_0=0, \qquad \alpha_1=\alpha_2=\frac12, \qquad \beta_1=\beta_2=\frac12.\]Then
\[x_1=\sqrt{\frac12}\eta_1,\] \[x_2=\sqrt{\frac12}x_1+\sqrt{\frac12}\eta_2,\]where \(\eta_1,\eta_2\) are independent standard Gaussian variables.
The forward conditional variances are
\[\operatorname{Var}(x_1\mid x_0)=\frac12\]and
\[\operatorname{Var}(x_2\mid x_0) = \frac12\left(\frac12\right)+\frac12 = \frac34.\]Applying the analytic posterior formulas from Section 5,
\[\tilde\beta_2 = \frac{1-\bar\alpha_1}{1-\bar\alpha_2}\beta_2 = \frac{1/2}{3/4}\frac12 = \frac13.\]Because \(x_0=0\), the posterior mean simplifies to
\[\tilde\mu_2(x_2,0) = \frac{\sqrt{\alpha_2}(1-\bar\alpha_1)} {1-\bar\alpha_2}x_2 = \frac{\sqrt2}{3}x_2.\]Thus,
\[\boxed{ q(x_1\mid x_2,x_0=0) = \mathcal{N}\!\left( x_1;\frac{\sqrt2}{3}x_2,\frac13 \right). }\]A correct sample from this conditional is
\[x_1^{\mathrm{sample}} = \frac{\sqrt2}{3}x_2 + \sqrt{\frac13}\xi, \qquad \xi\sim\mathcal{N}(0,1),\]with \(\xi\) independent of \(x_2\).
Now average over \(x_2\sim q(x_2\mid x_0=0)\). The generated previous state has variance
\[\begin{aligned} \operatorname{Var}(x_1^{\mathrm{sample}}\mid x_0=0) &= \frac{2}{9}\operatorname{Var}(x_2\mid x_0=0) +\frac13\\[4pt] &= \frac{2}{9}\frac34+\frac13\\[4pt] &= \frac12. \end{aligned}\]We have moved from variance \(3/4\) at \(x_2\) to the correct variance \(1/2\) at \(x_1\), despite adding fresh noise.
If we returned only the posterior mean,
\[x_1^{\mathrm{mean}}=\frac{\sqrt2}{3}x_2,\]its variance would instead be
\[\operatorname{Var}(x_1^{\mathrm{mean}}\mid x_0=0) = \frac{2}{9}\frac34 = \frac16.\]The mean-only result is a conditional estimate, but it does not reproduce the required distribution of \(x_1\).
This example uses the known analytic posterior to isolate the sampling principle. It does not claim that the learned generator knows \(x_0\), or that every learned reverse trajectory decreases its error monotonically. The general point is that sampling must represent conditional uncertainty, whereas returning a mean removes it.
D.2 Mathematical timesteps and zero-based array indices
The equations in this post use
\[t=1,\ldots,T\]for the forward noise steps, with \(x_0\) reserved for the clean image.
Code commonly stores the schedule in an array indexed by
\[k=0,\ldots,T-1, \qquad k=t-1.\]Accordingly,
\[\texttt{betas}[k]=\beta_{k+1},\]and
\[\texttt{alphas\_cumprod}[k] = \bar\alpha_{k+1}.\]The authors’ implementation uses this zero-based convention: its schedule index \(0\) corresponds to an image after the first noising step. Therefore, its “no noise when index equals zero” condition means the final mathematical transition \(x_1\rightarrow x_0\), not a network evaluation on the clean input \(x_0\). (DDPM implementation)
This offset affects both the coefficients retrieved from arrays and the timestep passed to the network. Training and sampling must use the same convention.
D.3 Optional clean-image clipping
Equation (14) uses the unmodified noise-to-mean parameterization. The original implementation also supports clipping the predicted clean image to the data range before computing the reverse mean. (DDPM implementation)
First compute
\[\hat x_{0,\theta}(x_t,t) = \frac{ x_t-\sqrt{1-\bar\alpha_t}\epsilon_\theta(x_t,t) }{ \sqrt{\bar\alpha_t} }.\]Then define
\[\hat x_{0,\theta}^{\mathrm{clip}} = \operatorname{clip}\!\left( \hat x_{0,\theta},-1,1 \right).\]For \(t\geq2\), use the clipped estimate in the posterior-mean formula:
\[\mu_\theta^{\mathrm{clip}}(x_t,t) = \tilde\mu_t\!\left( x_t,\hat x_{0,\theta}^{\mathrm{clip}} \right).\]This clips the estimated clean image, not the noisy state \(x_t\). The noisy state is a continuous random vector and is not restricted to the clean image’s value range.
Without clipping, this computation is algebraically equivalent to Equation (11). When clipping changes the clean estimate, it also changes the reverse mean; the result is no longer the unmodified expression in Equation (14). At the final step, the clipped clean estimate can be returned directly.
Clipping is therefore an implementation choice layered on top of the derivation, not a consequence of the Gaussian posterior calculation.
References
- Variational Autoencoder - Model, ELBO, loss function and maths explained easily!
- Understanding Variational Autoencoders (VAEs), Variational Autoencoders | Generative AI Animated
- The Breakthrough Behind Modern AI Image Generators - Diffusion Models Part 1
- Auto-Encoding Variational Bayes (VAE Paper)
- Denoising Diffusion Probabilistic Models (DDPM Paper), Denoising Diffusion Implicit Models (DDIM Paper)
- Diffusion Model Paper Explanation, PyTorch Implementation Walk Through and corresponding github repo
- diffusion-DDPM-pytorch & diffusion-DDIM-pytorch
- An Optimal Control Perspective on Diffusion-Based Generative Modeling & SDE/ODE Interpretation of Diffusion Model